Runs, debugging, and traces
A run is not only “successful” or “failed.” Workrun keeps the workflow snapshot, state changes, node events, model and tool activity, Python logs, and runtime diagnostics in the run workspace. Use that record to answer one concrete question: where did this run stop, with which inputs, after which result, and what should change next?
Do not reverse-engineer a cause from the final answer. Build the evidence trail first, then change a prompt, code, schema, permission, or model configuration.
Deeplink-triggered runs
Section titled “Deeplink-triggered runs”App and Workflow runs started through external links are labeled External link in history. New runs require confirmation on the corresponding list page. App output opens in a drawer on the list; Workflow output opens in a drawer on its detail page. Execution completion keeps that page visible, and saved output remains accessible through history.
Reopening the same original request with a requestId opens its existing run instead of executing again. See Open and run through Deeplinks for link formats, input, and deduplication rules.
After a failure, narrow the scope in five steps
Section titled “After a failure, narrow the scope in five steps”- Open this run from run history and confirm its workflow version, run input, and start time. Do not mix it with another workflow revision or chat turn.
- In the node timeline, find the last node that is not complete. It is the investigation starting point, not necessarily the root cause.
- Inspect the events around that node. Confirm that upstream nodes actually published the state it needs and that it has permission to read it.
- Inspect evidence for the node type: model messages and tool activity for an Agent; stdout, stderr, and structured result for a Process App; field values and the selected exit for a condition.
- Confirm external side effects before resuming or retrying. After fixing configuration or code, run the same input again and add reproducible issues to an evaluation suite.
This sequence separates “what happened” from “what to change”: establish facts first, then choose the change.
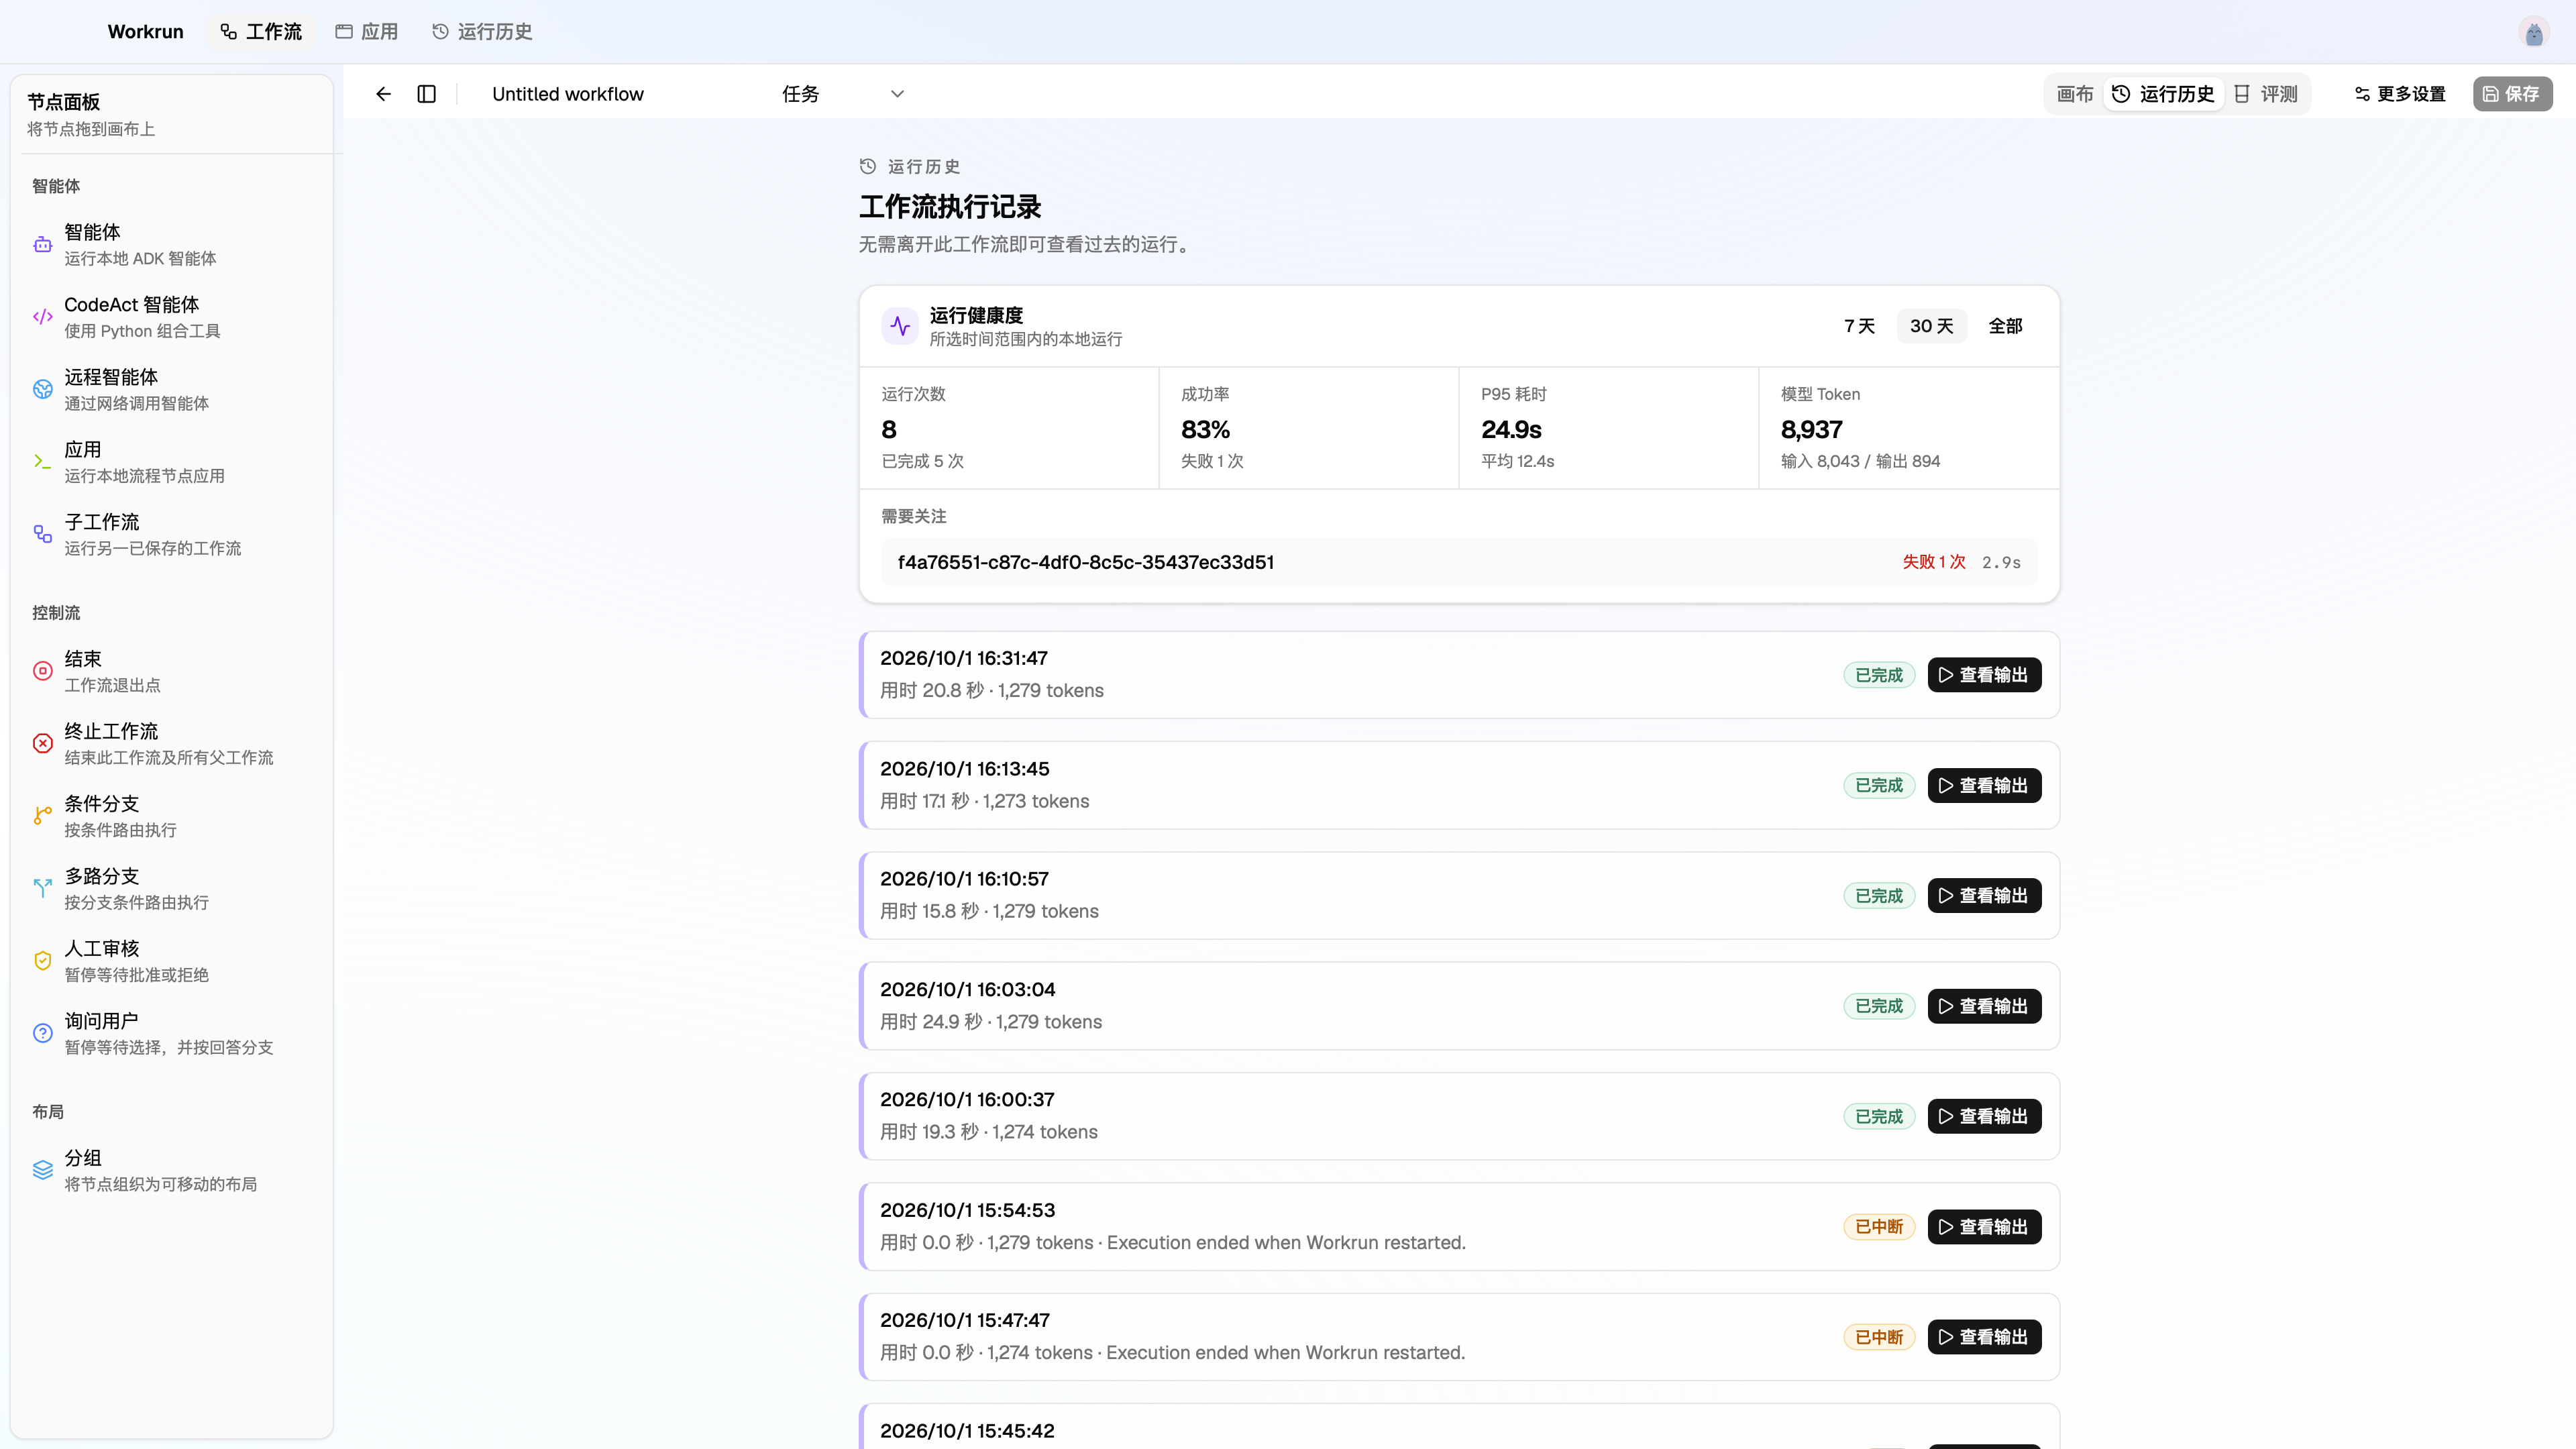
Within one workflow, run history shows both health over a time range and the status, duration, and tokens for every execution. Select the run to investigate here, then choose View output to enter its run workspace.
Read the run status before taking action
Section titled “Read the run status before taking action”| Status | What it means | Next step |
|---|---|---|
queued / running |
The run is queued or still executing. | Wait for more events. If no events arrive for an unusual time, inspect timeouts on the active model or tool. |
waiting_for_input |
Human review, a question response, or tool confirmation is pending. | Complete the action in the run panel; do not treat it as a failed run. |
completed |
This execution has ended. | Check final state and diagnostics. If the result is wrong, trace upstream from the node that produced the wrong value. |
failed |
A node or runtime step could not complete. | Read the error and cleanup/cancellation evidence, then Run again to create a new task. |
cancelled |
A person stopped the run. | Verify external outcomes; create a new task if execution is needed again. |
interrupted |
Execution was interrupted or a recovery check could not pass. | Read the reason in the output panel and try recovery, or choose Stop tracking. |
Waiting for input is a resumable pause. Failed or stopped tasks must Run again; only application-interrupted tasks can recover their original checkpoint.
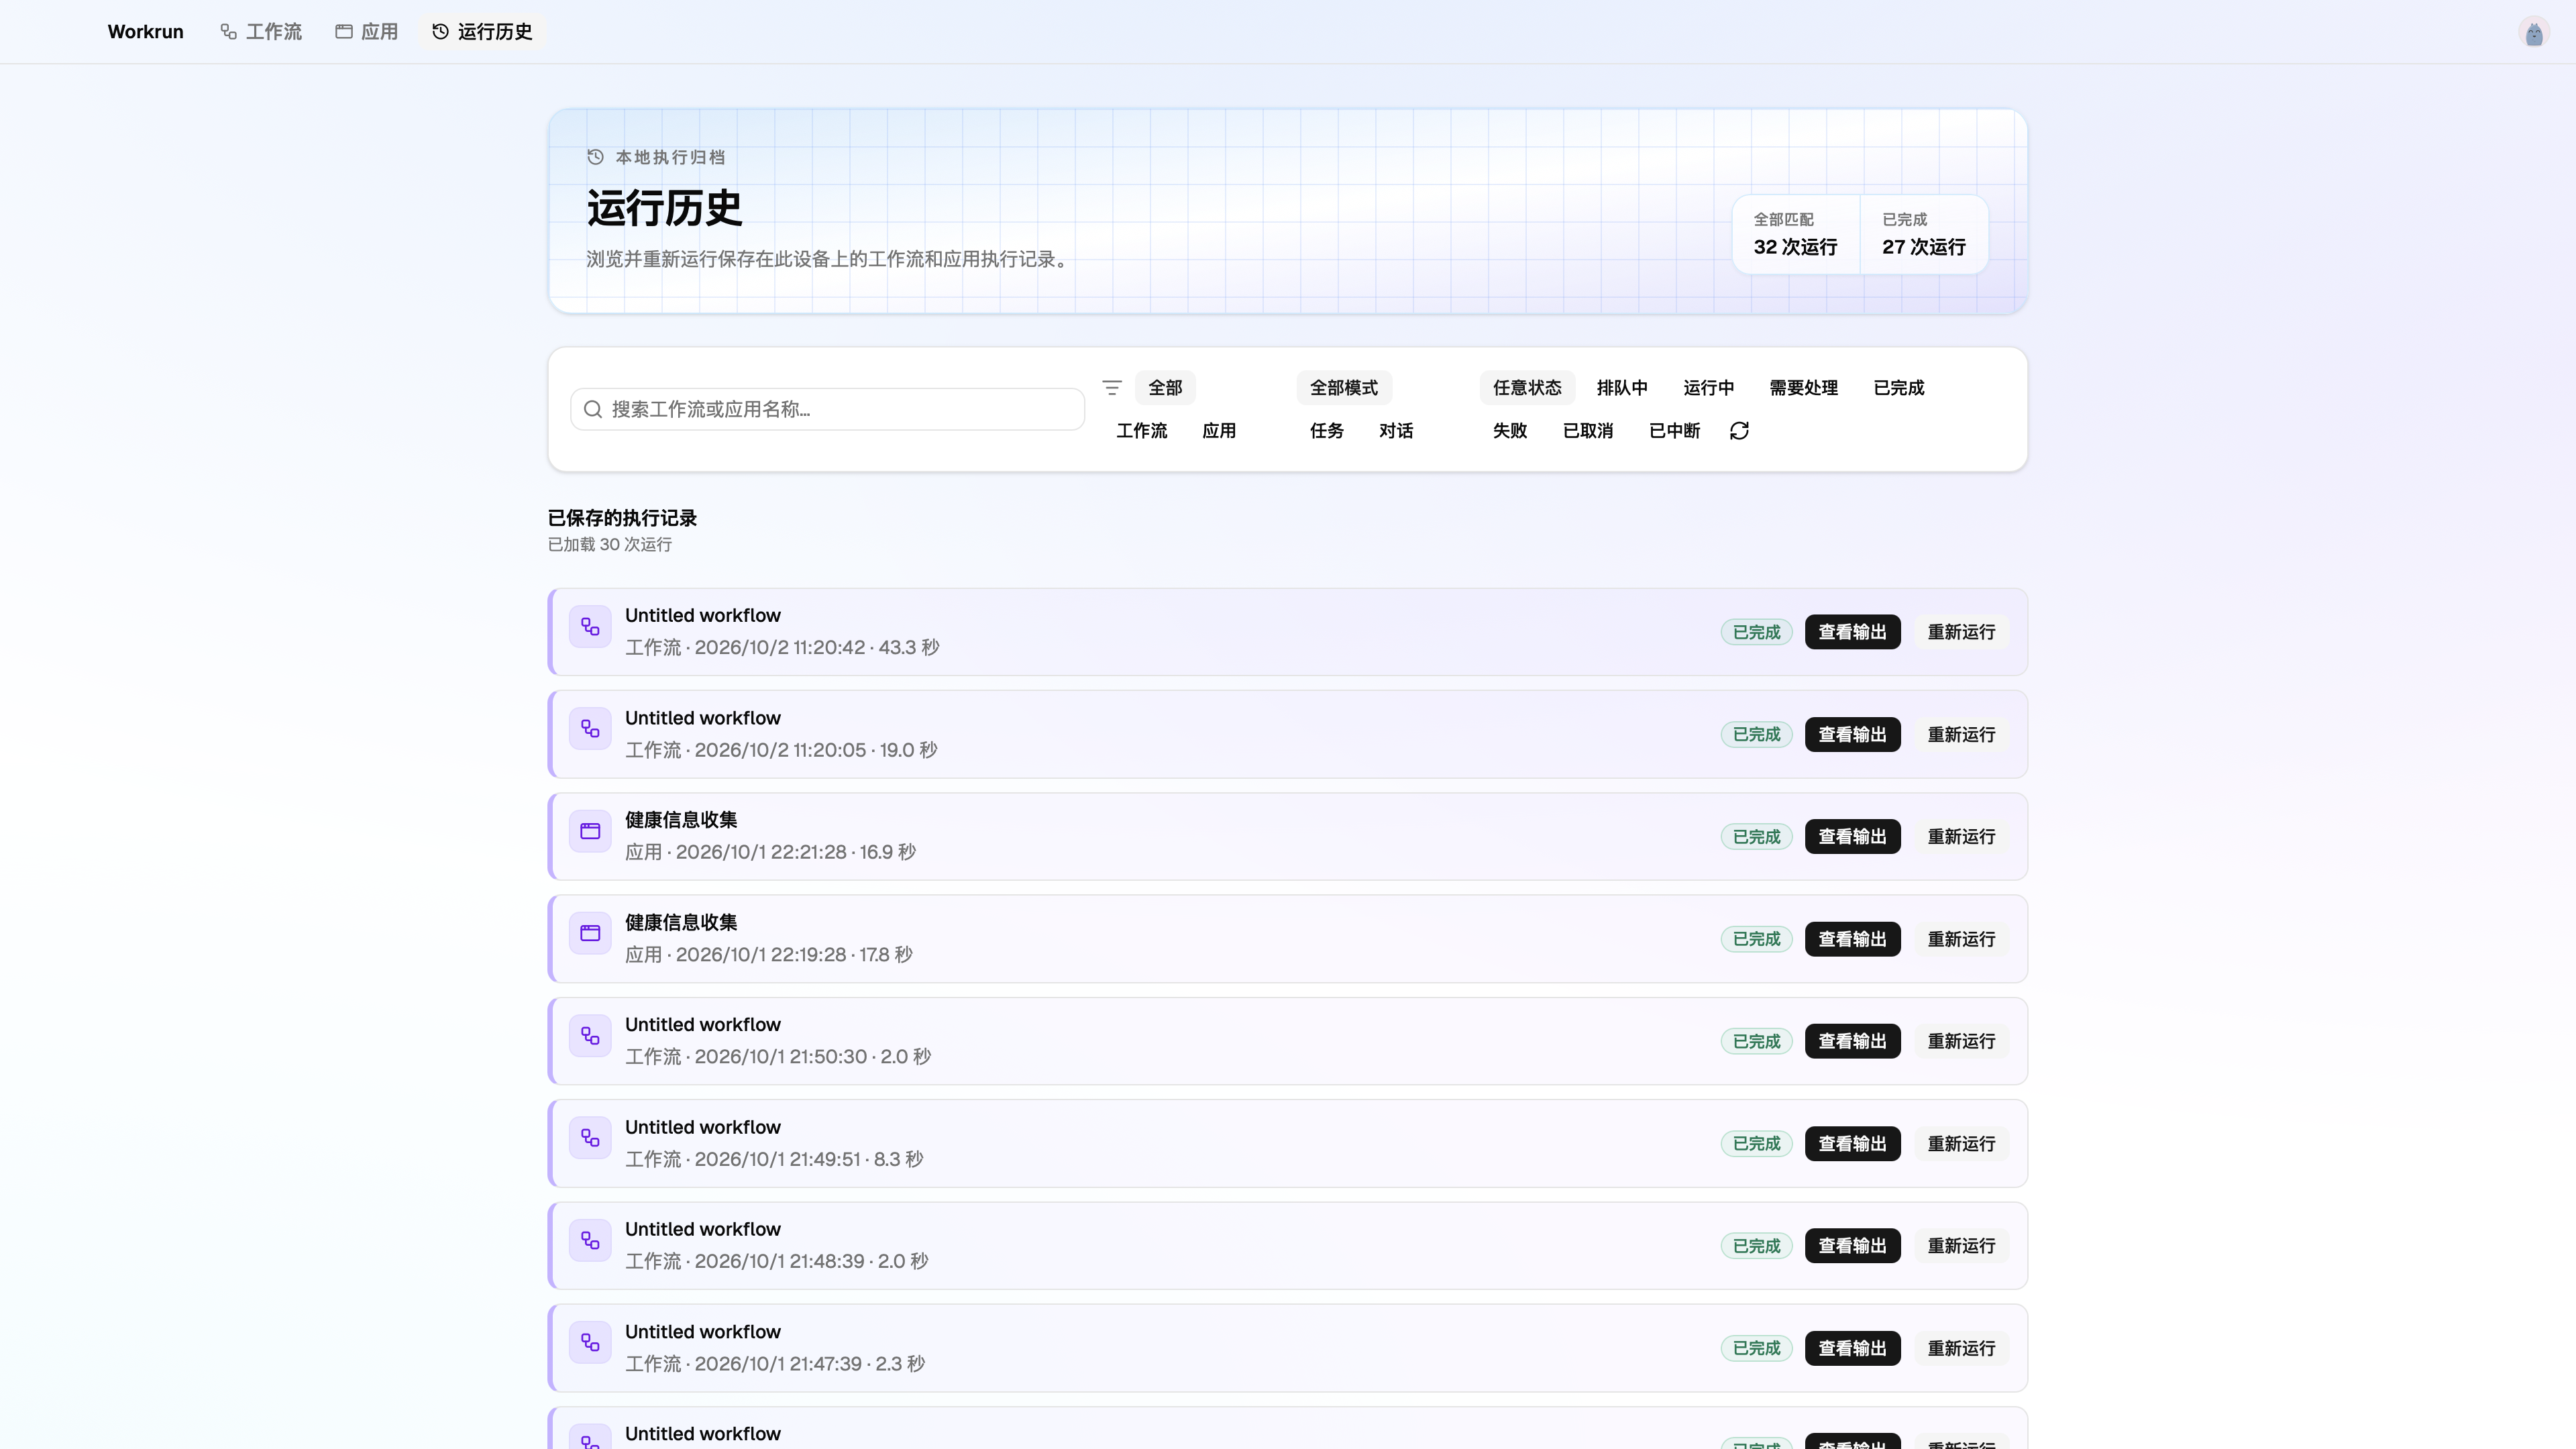
Global Run history combines local workflow and App executions in the current workspace. When a run’s source is unclear, or when you need to find interrupted and failed App runs, filter by name, target type, mode, and status before opening its output.
Run Center and restart recovery
Section titled “Run Center and restart recovery”The Run Center lists runs in the current workspace that need follow-up: queued, running, waiting for input, and interrupted runs whose tracking has not been dismissed. Separate runs of the same workflow appear independently. Open a run to handle questions, human reviews, or tool authorizations on its node output cards, with other node results available for context.
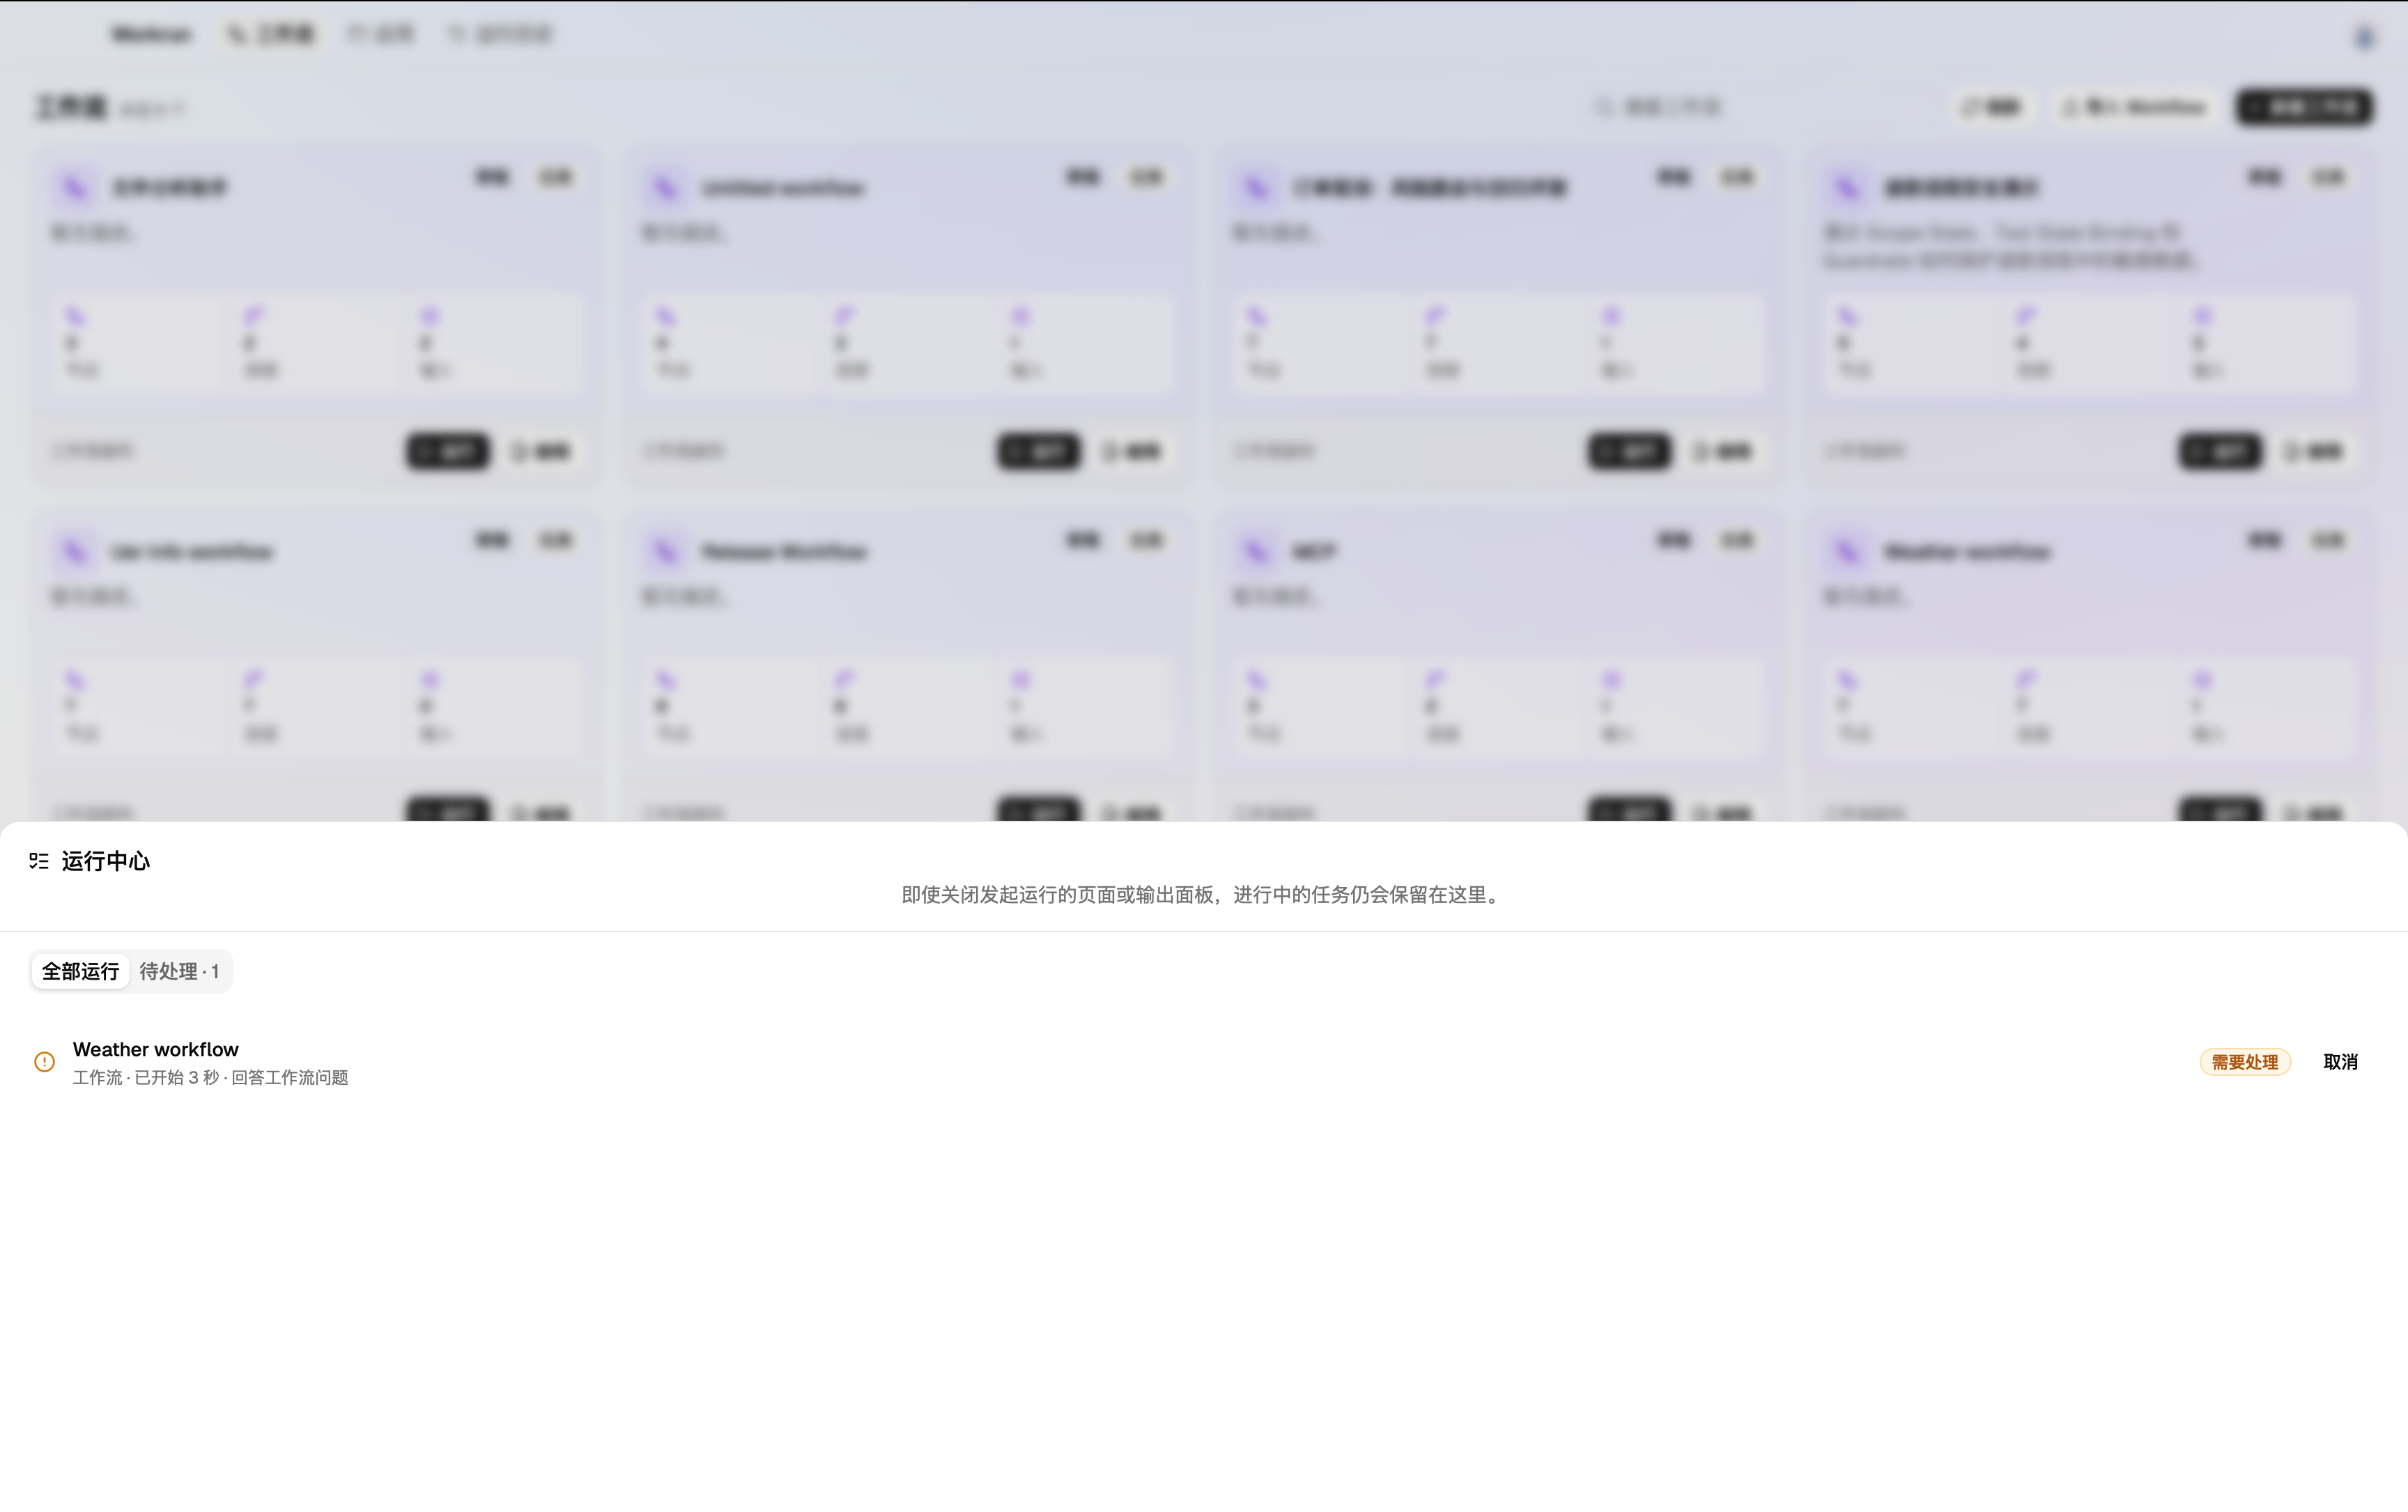
This run is waiting for a question response. Select it to open its output and answer on the question card in the node messages. You can inspect existing node results before responding or return later.
| State when the app exits | Behavior after restart |
|---|---|
| Waiting for input with a pending request | Keep the wait and request; continue from its original card. |
| Queued with complete saved execution information | Keep it queued; check dependencies and any recovery checkpoint before dispatch. |
| Running, waiting without a valid request, or missing saved execution information | Mark interrupted and retain the reason, without creating a fresh run. |
| Completed, failed, or cancelled | Preserve the original status and history. |
Evaluation executions do not use the ordinary task interaction recovery flow. Standalone App executions also cannot resume in place; verify their original outcome before running again.
Choose Try to recover in workflow output to check and continue the same run. A failed recovery retains the record and displays the reason; retry after resolving it. If a remote task is being reconciled automatically, wait for that result. Stop tracking removes an interrupted run from the Run Center and stops recovery scheduling while keeping history. It does not cancel remote work or execute compensation. Completed, failed, or cancelled runs can use Run again to create a new task.
The run workspace: what each piece of evidence answers
Section titled “The run workspace: what each piece of evidence answers”| Evidence | Ask first | Common conclusion |
|---|---|---|
| Node timeline and events | Which node stopped? In what order did completion, waiting, and failure occur? | The issue belongs to an Agent, App, tool, condition, or human action. |
| Run input and upstream state | Are input keys, types, and values correct? Did an upstream node publish the required field? | A required value is missing, a key differs, or the downstream node lacks read access. |
| Model messages and structured output | What did the Agent actually see? Does its output meet the contract? | Prompt, model configuration, structured schema, or state boundary needs adjustment. |
| Tool activity | Were parameters, approval, limits, and returned shape correct? | Tool description, state binding, permission, or the service needs repair. |
| Process App stdout / stderr | Where did Python fail? Did it return the expected JSON? | Dependency, environment, business logic, or App data contract is wrong. |
| Final state | Which fields actually reached workflow output and downstream nodes? | A value was not published, was overwritten, or sensitive-data visibility needs redesign. |
| Runtime diagnostics | Which node, model, or tool used time, tokens, or calls? | Limit tool calls, shorten context, select another model, or investigate a bottleneck. |
The record preserves the target snapshot, final state, and event sequence for this run. Anchor your investigation to that evidence before changing the current draft; otherwise it is hard to know whether a change solved the same problem.
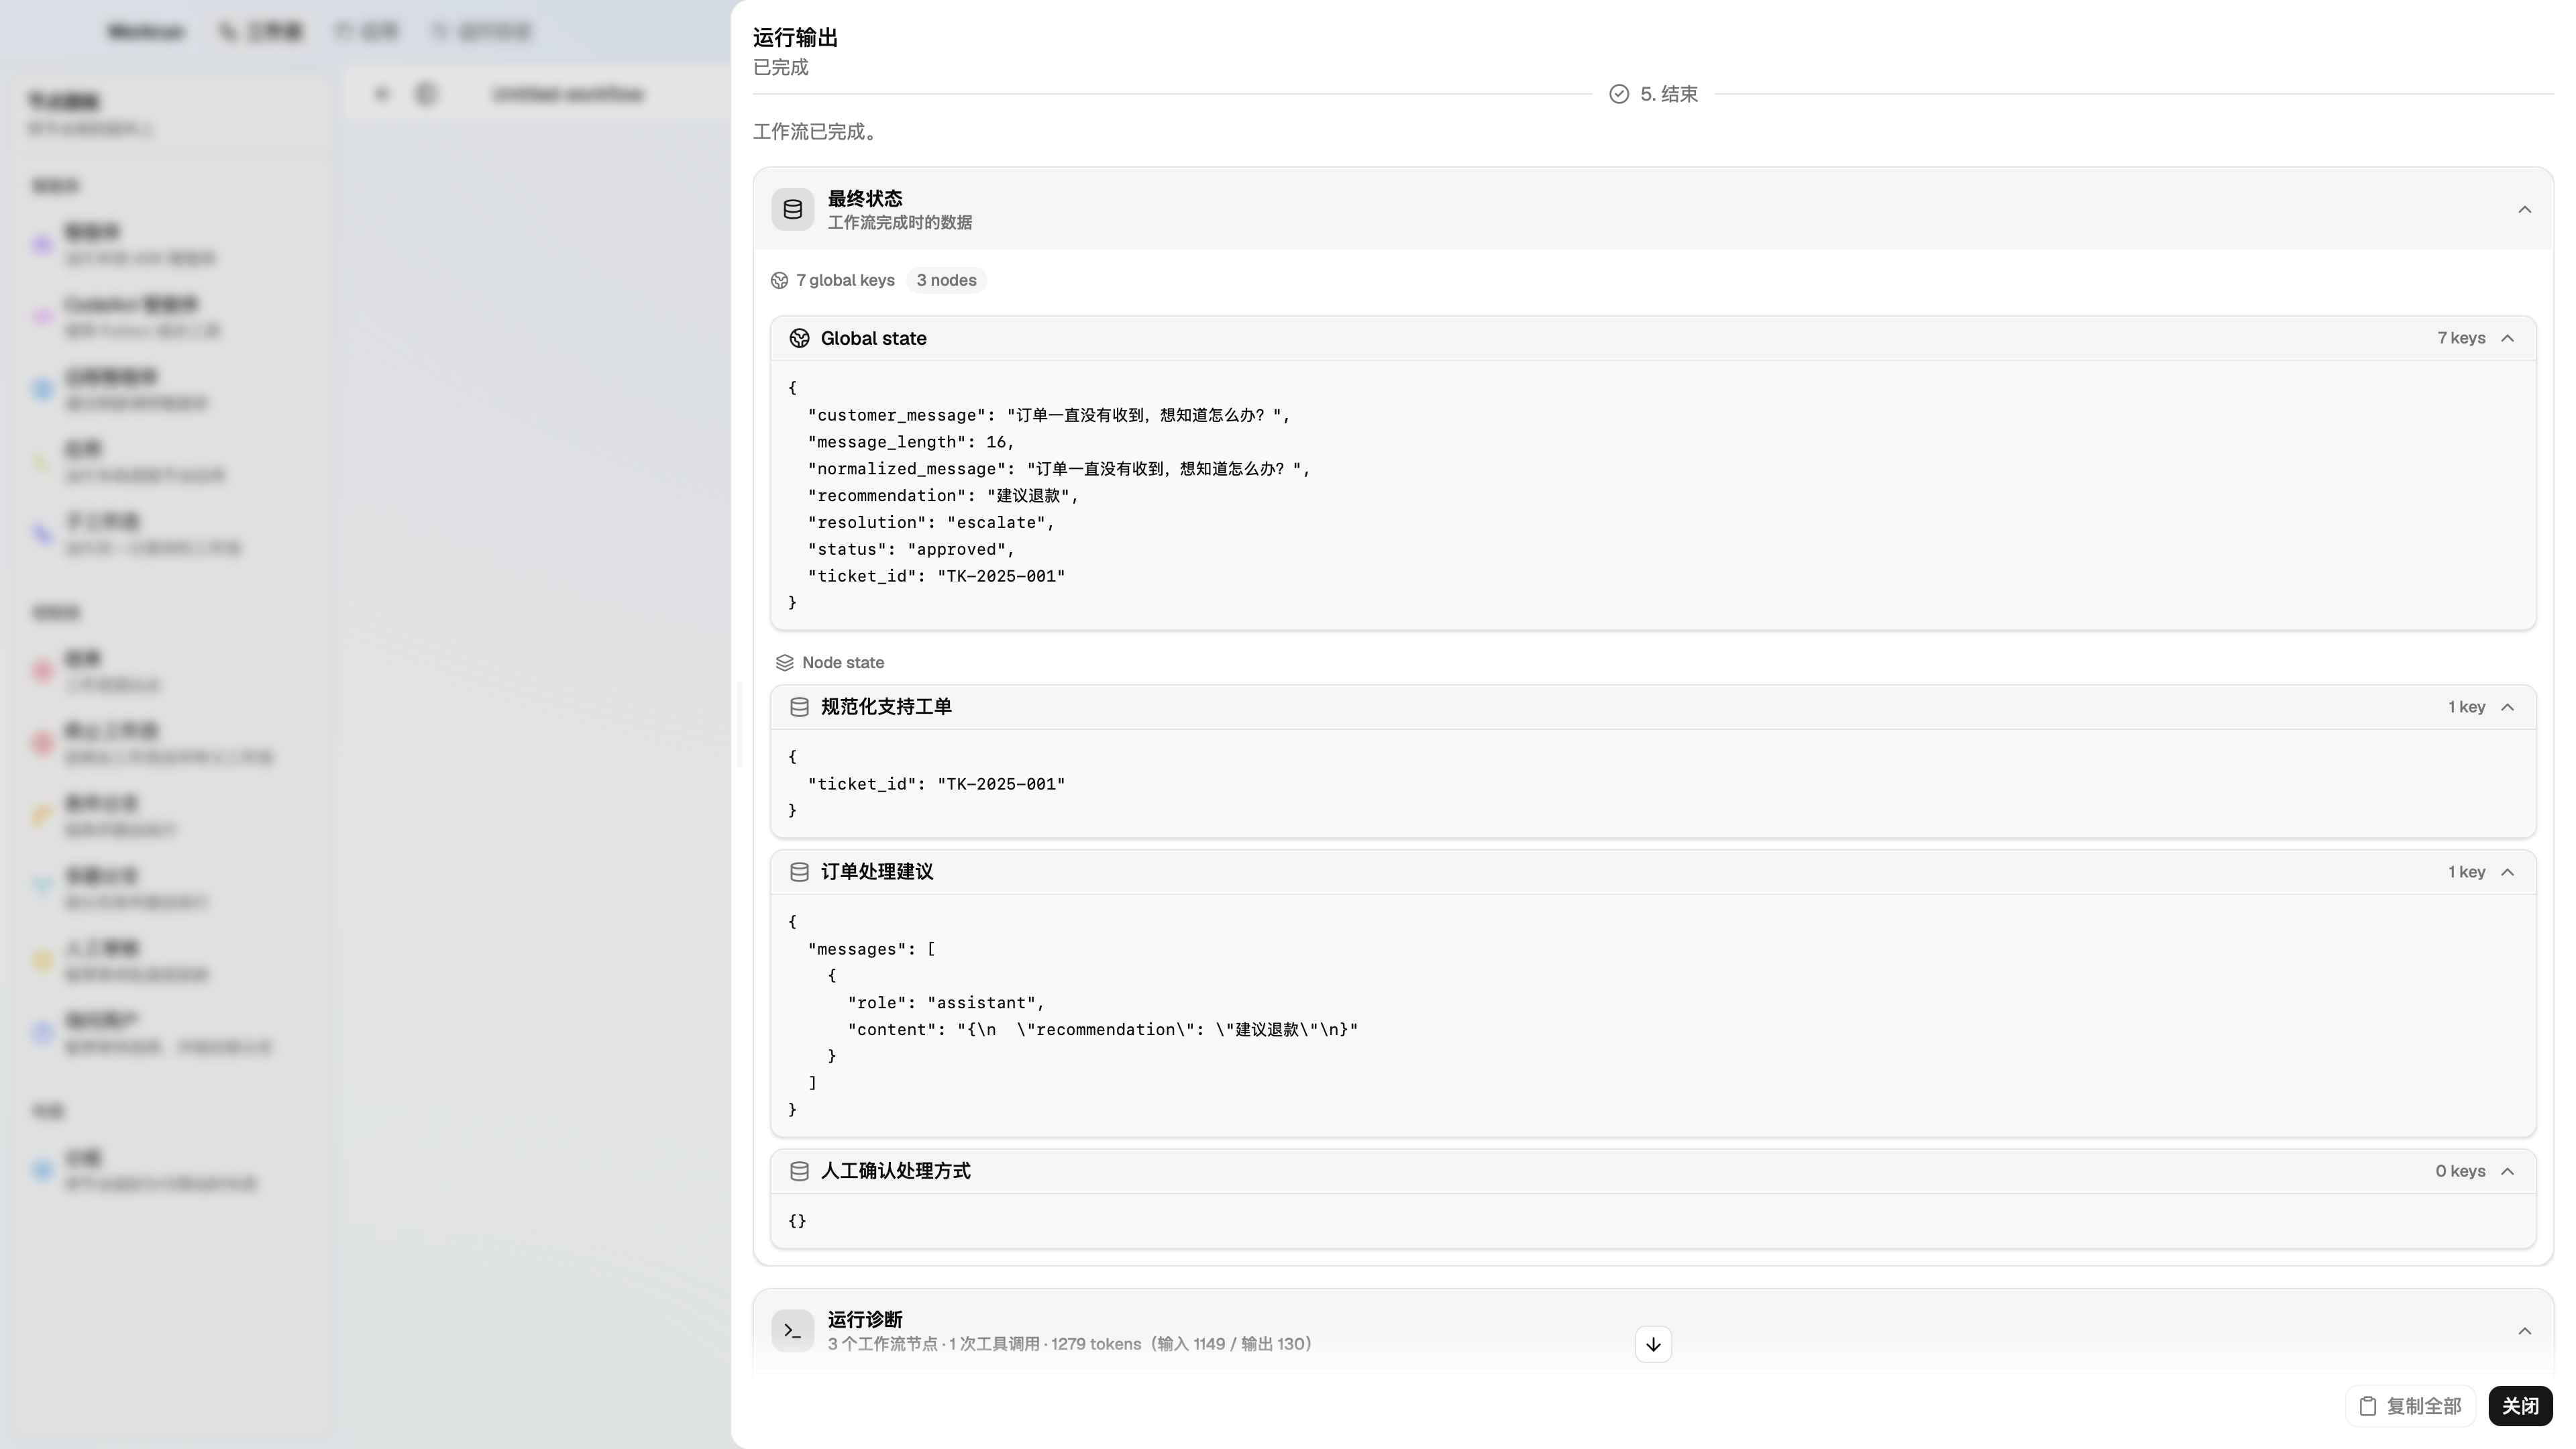
Inspect global state first to confirm that workflow outputs and downstream dependencies exist. Then expand node state to trace a value to its producer. The messages and ticket ID shown are demonstration data; treat sensitive fields according to state access and redaction rules in real runs.
Diagnose by node type
Section titled “Diagnose by node type”Agent: inspect input before the decision
Section titled “Agent: inspect input before the decision”Check that the Agent uses a configured model and sees the required input, that its instructions state tool-use conditions and output boundaries, and that structured output conforms to its schema and publishes fields needed downstream. If results vary, run the same input several times before changing the prompt, model, or acceptance rule.
Do not stop because a natural-language response looks plausible. Conditions and downstream nodes should use stable structured fields, not inferred values in a response.
Tool Apps, MCP, and remote tools: inspect the call boundary
Section titled “Tool Apps, MCP, and remote tools: inspect the call boundary”First confirm the tool is enabled in that Agent’s tool list and its name, description, and Agent instructions explain when to use it. Then verify that arguments come from intended authorized state keys, confirmation/limits/timeouts allow the call, and the returned value matches its declared schema—not only that a service returned HTTP success. For a Tool App, inspect its stdout and stderr too.
For a tool that sends, writes, or deletes, confirm in the external system whether the action already happened before retrying.
Process Apps: keep logs and returned data separate
Section titled “Process Apps: keep logs and returned data separate”Process App stdout and stderr are debugging evidence; process.result({...}) is the structured result passed to the workflow. Check code execution, dependencies and environment, the returned App contract, and whether keys needed downstream are published on the node.
When an App works independently but fails in a workflow, check workflow-state input, read access, and published output keys before changing Python code. See Use Python Apps.
Conditions, state, and human nodes: inspect visible data, not guessed routing
Section titled “Conditions, state, and human nodes: inspect visible data, not guessed routing”A condition should read an explicitly published stable field. When routing is wrong, inspect the producing output, publication setting, condition key, and the exit actually selected. Human review and questions pause at a checkpoint; once resolved, the run continues without rerunning completed nodes.
For state boundaries, redaction, and checkpoints, see Workflows and state.
Remote Agents: distinguish local Stop from remote completion
Section titled “Remote Agents: distinguish local Stop from remote completion”After workflow failure or user Stop, Workrun sends one best-effort CancelTask request for unfinished remote calls with a known task ID, without runtime confirmation. Node messages show the request and returned status without replacing the original error. Known terminal tasks are skipped; submissions without a task ID remain unknown and are not automatically resubmitted.
A failed or timed-out cancellation is shown as unconfirmed. There is no preliminary query, automatic polling, cancellation retry, or startup continuation of cancellation. Failed or stopped tasks must Run again. Application-exit interruptions retain their existing recovery path. Remote cancellation does not promise business undo. See Remote Agents and A2A task handling.
Run output presents automatic App compensation and remote cancellation results in the owning node messages.
After App compensation, fix the problem and run again
Section titled “After App compensation, fix the problem and run again”When a workflow fails, successful App calls with a compensation entry are cleaned up automatically, including successful Tool App calls inside an Agent. Check compensation status in the corresponding node messages and verify unfinished or unknown resources. Once cleanup starts, checkpoint continuation cannot reuse cleaned-up results. Fix the problem and choose Run again to create a new task for a fresh business execution; the original retains failure and cleanup evidence.
Stop and normal completion do not trigger automatic cleanup. See App failure compensation for configuration and exception handling.
Confirm side effects before recovering from a checkpoint
Section titled “Confirm side effects before recovering from a checkpoint”Only application-interrupted tasks can recover from a checkpoint. Failed or stopped tasks use Run again, which creates a new business execution; it does not resume their checkpoint.
For an application-interrupted task, Workrun checks the checkpoint and operation journal before recovering in the original task. Saved results can be reused; unknown outcomes require reconciliation and cannot be blindly submitted again. Unsupported recovery contracts block continuation.
After a workflow failure, inspect the failed node and the automatic App cleanup or remote cancellation messages. Verify external resource state before choosing Run again: a new task repeats business execution and does not undo effects left by the previous task.
Use runtime diagnostics to find slow and expensive work
Section titled “Use runtime diagnostics to find slow and expensive work”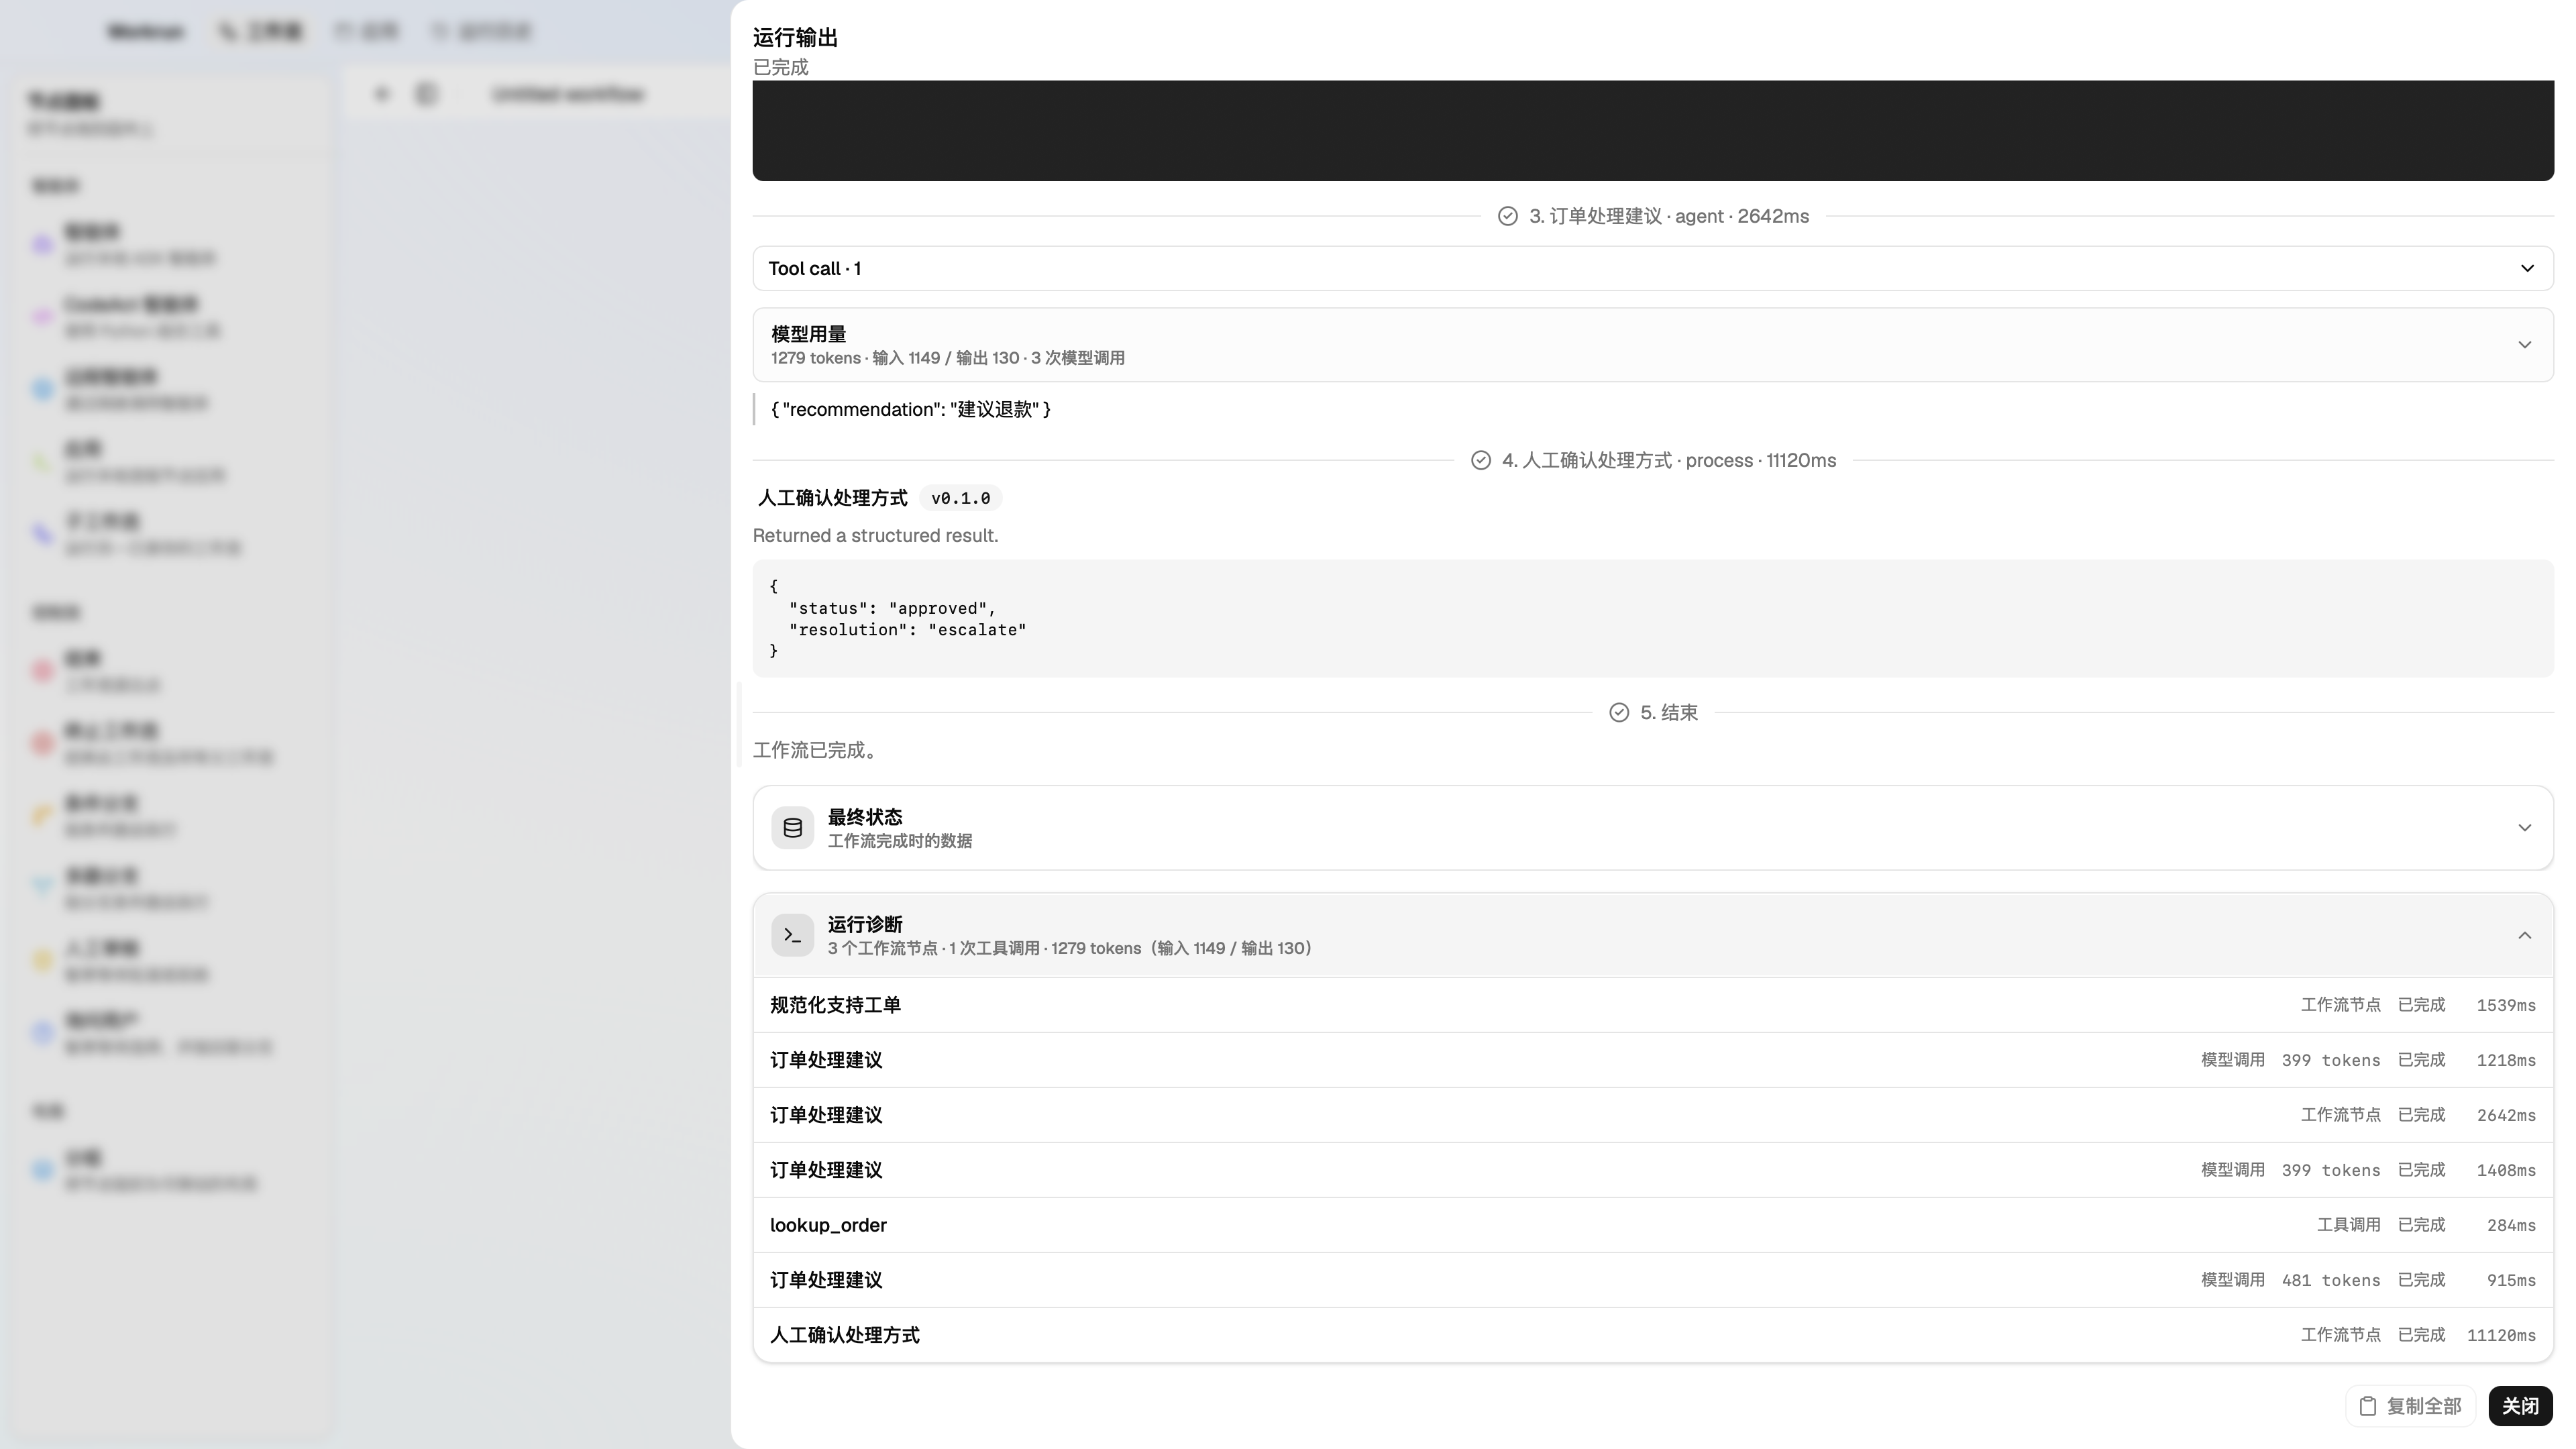
Diagnostics list workflow-node events, model calls, and tool calls for the same node separately. For example, compare an Agent’s model usage with the duration of the lookup_order tool to determine whether the bottleneck is the model, tool, or Process App.
Runtime diagnostics summarize workflow nodes, tool calls, and model calls with duration and status. When the Provider returns usage, they also show input, output, and total tokens plus estimated cost. Use them to determine whether a model call became slow, a tool is timing out, calls are excessive, or token growth comes from context, output, or reasoning.
Return to events and inputs for a one-off anomaly. For a repeated pattern, use an evaluation suite or version comparison. See Evaluations and quality gates for batch regression checks and publishing gates.
Connect traces to your observability system
Section titled “Connect traces to your observability system”The run workspace remains the first source of evidence for one execution. To investigate Workrun together with other team services, enter an OTLP/gRPC collector endpoint in Settings → Logs. Saving a new endpoint requires an app restart before it takes effect.
Before configuring export, confirm that the collector and network policy allow only intended recipients, traces do not contain sensitive content or credentials that must not leave the device, and a non-sensitive run in an isolated environment verifies connection, fields, and retention first.
OTLP is a diagnostic export. It does not replace local run records, state boundaries, or inspecting individual results.
Use Langfuse
Section titled “Use Langfuse”Deploy infra/langfuse independently for Langfuse and a Collector, or use an existing OTLP backend. See Deployment. Configure the desktop with the Collector’s OTLP/gRPC address, not the Langfuse UI URL: locally, http://127.0.0.1:4317. The Collector supplies project authentication and forwards to Langfuse /api/public/otel. Remote desktops need a reachable, protected collector endpoint.
Export covers conversations, workflows, nodes, model generations, and tool observations, correlated with session/run/node/call IDs. Metadata can include the current account identity. Input/output capture is off by default; enable Settings → Logs → Export conversation and workflow content separately and restart. Disabling content capture does not disable metadata export. The supplied configuration discards metrics and requires neither Langfuse AI Gateway nor a LiteLLM Langfuse callback.
Langfuse helps investigate model, tool, and orchestration timing. It does not replace local checkpoints or run history; the Server currently has no additional NestJS distributed-trace instrumentation.
File results and local storage
Section titled “File results and local storage”History stores file outputs as artifact references; the actual files remain in the current workspace’s local artifacts directory. Export files from the results, preview images and videos, or open PDFs. Access depends on the corresponding local snapshots: keeping run records without their artifact files cannot restore file contents.
Personal and Team run history, chat sessions, and pending approvals are isolated by workspace. Switching modes shows only the current workspace; switching back restores access to its records. Team run history and artifacts also remain on the local device. Publishing a workflow does not upload them to the team server, and another device or team member does not automatically receive these results. Backups or device migrations need both the run database and the corresponding workspace artifact files.