Evaluations and quality gates
An evaluation is not a scorecard for whether a model “looks good.” It repeatedly checks fixed inputs: whether Agent output is correct, tools were used correctly, and sensitive information did not escape. Every Case keeps its verdict, evidence, and failure reason so teams can separate model variation from a real regression.
Evaluation input becomes the initial workflow State for that run. Results are bound to the workflow snapshot used at run time, so later draft edits cannot rewrite a historical conclusion.
Current limitation: evaluation hard-rejects Process Apps, CodeAct Agents, and Remote Agents.
if_else,switch, andterminatedo not have this hard restriction. However,Human ReviewandAsk User Questionneed a person to act, so they are not stable unattended evaluation steps. A subworkflow also fails if it contains a restricted node. For repeatable Agent regression checks, use aStart → Agent → Endtest workflow and provide its required normalized data as run input; verify end-to-end flows with ordinary runs and Runs, debugging, and traces.
Why evaluation limits these nodes
Section titled “Why evaluation limits these nodes”An evaluation must run the same Case repeatedly, compare versions, and avoid surprising changes to real systems. Restricted nodes do not yet have a shared evaluation adapter:
- A Process App can run arbitrary local Python, read files, access a network, or write to internal systems. The same input may not produce the same result and may have real side effects.
- A CodeAct Agent or Remote Agent depends on an external runtime, service, or network state. Without replay or a test endpoint, result, cost, and latency cannot be compared reliably.
- Human Review and Ask User Question require a person’s decision. An evaluation should not silently approve, reject, or answer on that person’s behalf.
Evaluation therefore rejects execution boundaries it cannot control safely and deterministically, rather than implying they ran in an isolated environment. if_else, switch, and terminate consume existing state without independently calling an external system, so they do not have the same hard restriction.
This does not make those nodes less important. Use ordinary runs, run history, and end-to-end manual verification to check their state transfer, permissions, recovery, and real side effects.
Direction for future integration evaluation
Section titled “Direction for future integration evaluation”The goal is not to remove the limit, but to let more nodes participate behind controlled boundaries. Tool Apps and MCP already support exact-match fixtures; adapters for the remaining restricted nodes are future directions, not commitments to a particular delivery date:
| Node or boundary | Evaluation adapter needed | What it could verify |
|---|---|---|
| Process App | Fixed input/output fixture or isolated project runtime | App data contract, state publication, and error handling. |
| Tool App and MCP (already supported) | Exact tool-and-argument fixture, optionally scoped to a node | Arguments, call count, response shape, and failure paths; unmatched calls are blocked. |
| Remote Agent / CodeAct Agent | Replay, test service, or constrained sandbox | Agent protocol, code-execution result, and cost boundary. |
| Human Review / Ask User Question | Preset approval, rejection, edits, or answers | State and routing after each human decision. |
| Subworkflow | Recursive check that internal nodes have compatible adapters | Parent/child inputs, outputs, and version combinations. |
Until adapters cover the remaining restricted nodes, split the quality strategy in two: use Agent evaluations to protect model behavior, and ordinary runs plus run history to verify the complete Workflow. This avoids bringing external side effects into a regression suite without ignoring real end-to-end risk.
Define the behavior you must protect first
Section titled “Define the behavior you must protect first”Do not start with “what score do we need?” Choose a behavior a change must not break, then express it as input and an observable expectation.
For customer-feedback triage, a first suite named “Customer feedback classification regression” should cover:
| Case type | Input characteristic | Behavior to protect |
|---|---|---|
| Common | Ordinary, complete request | Correct category, priority, and recommendation. |
| Edge | Missing or ambiguous information | Does not invent facts; marks missing information in structured output. |
| High risk | Refund, privacy, or account-security issue | Returns the correct priority and recommendation; does not expose sensitive fields. |
| Regression | A real issue that happened before | The original problem stays fixed, including the constraint that revealed it. |
One Case should describe one decidable behavior. The more realistic the input, the more assertions should focus on stable fields, tool behavior, and safety boundaries—not a word-for-word free-text response.
Create your first evaluation suite
Section titled “Create your first evaluation suite”- Open Evaluation suites in the workflow and create a Suite with a name and coverage statement.
- Create a Case with a name, description, and Input JSON. Its keys must match the workflow run-input contract.
- Add the most important output assertion first, then add tool and safety assertions only where risk requires them.
- Save and run the Suite. Every Case shows passed, failed, error, or skipped with execution evidence.
- After changing a prompt, node, model, or tool, rerun the same Suite and compare new failures, fixes, and persistent failures.
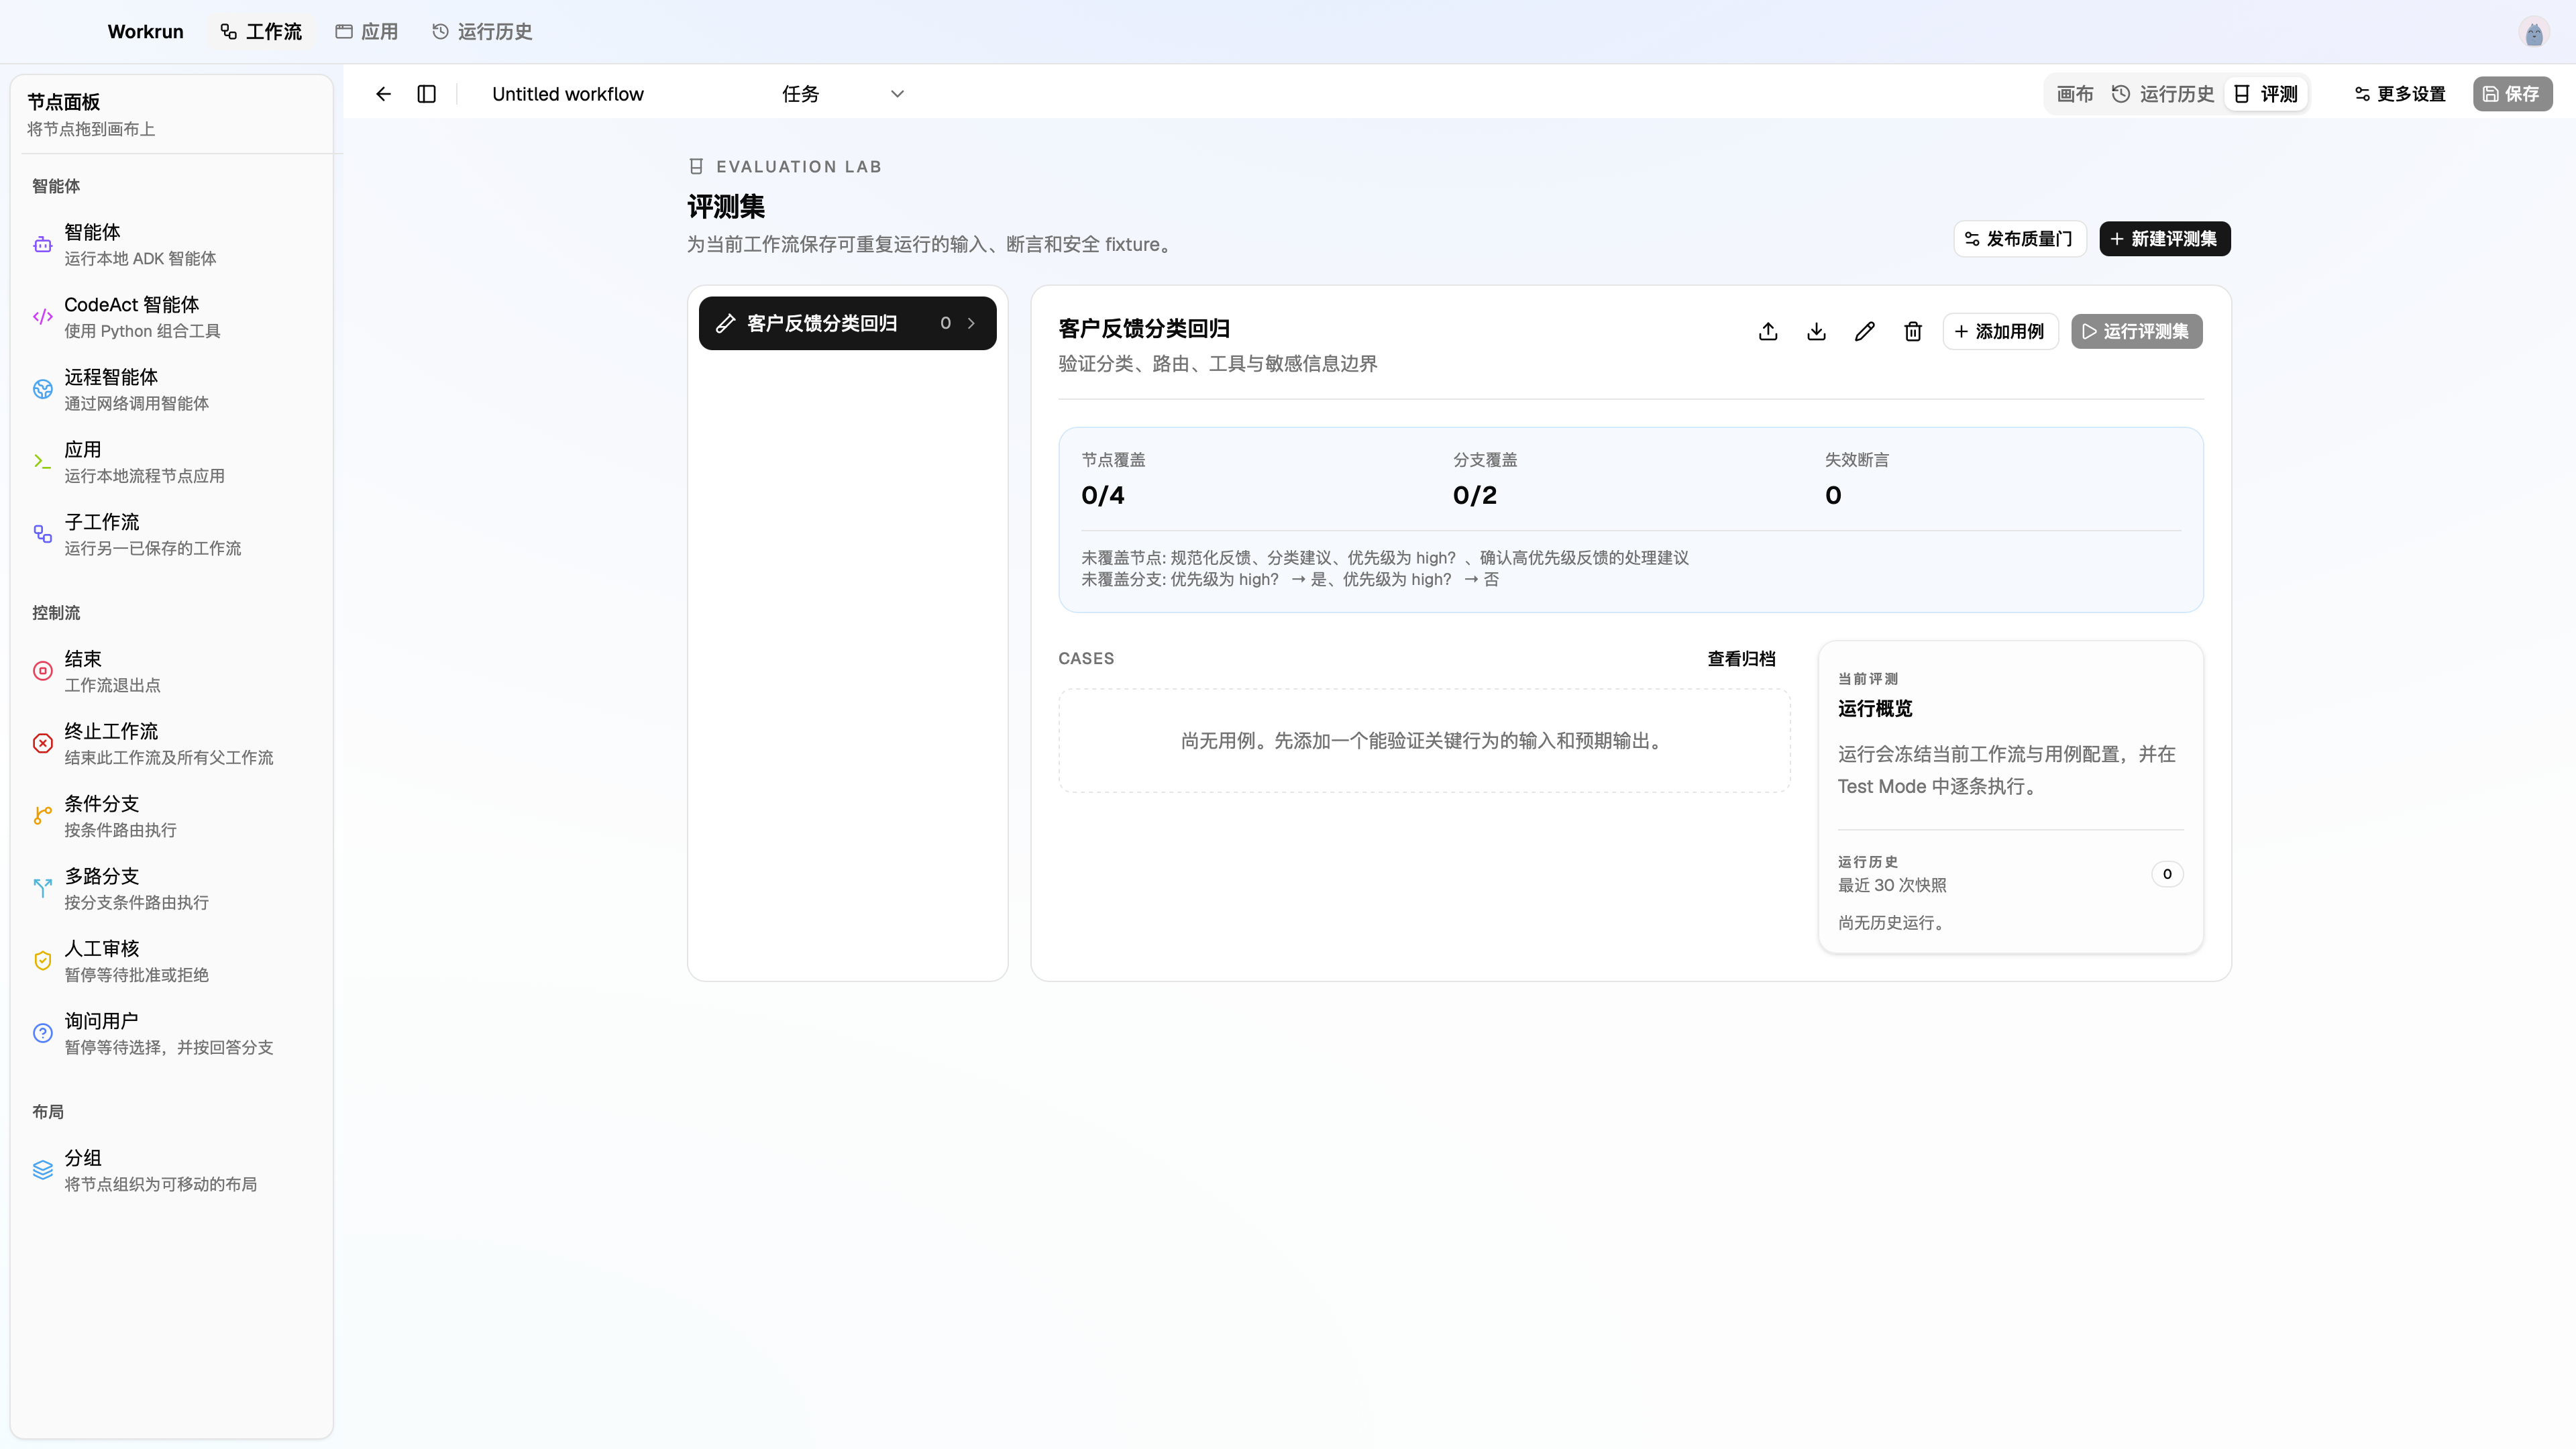
Example input JSON:
{ "feedback": "The CSV exported after the upgrade cannot be opened, and Finance must reconcile accounts this afternoon."}Do not assert only a response sentence for this input. At minimum, require priority to be high and require the classification Agent’s structured output to contain an actionable recommendation.
Complete example: classify a high-priority report correctly
Section titled “Complete example: classify a high-priority report correctly”The following configuration creates one Case in the “Customer feedback classification regression” Suite. For the most stable regression test, create or copy a test workflow containing only Start, the classification Agent, and End. The Agent should read feedback, or normalized_feedback must be a run input for the test workflow. Do not include Process or nodes needing human action in this evaluation flow.
1. Create the Suite and Case
Section titled “1. Create the Suite and Case”- Open Evaluation suites from the workflow header and create a Suite named “Customer feedback classification regression.” Describe it as “Validates Agent classification, tools, and sensitive-data boundaries.”
- Select the Suite and create a Case named “Classify Finance reconciliation blockage correctly.” Describe the expected behavior: a high-urgency issue needs an actionable recommendation.
- Under Workflow input → Input JSON, enter:
{ "feedback": "The CSV exported after the upgrade cannot be opened, and Finance must reconcile accounts this afternoon."}Top-level input JSON keys must match the workflow’s run-input keys. Do not add fields that exist only in a node’s private state.
2. Add final-output rules
Section titled “2. Add final-output rules”In Validation rules, add a rule and select Final output field. Add:
| Field path | Operator | Expected value | Why |
|---|---|---|---|
$.priority |
Equals | high |
Verifies a stable classification result. |
$.category |
Exists | None | Verifies that the classification field is present. |
$.recommendation |
Exists | None | Verifies that the recommendation field is present. |
These fields match the classification Agent’s structured output schema. An existence assertion only checks that a field is present; review the first result for actionable advice, then add a contains assertion if your requirements call for specific content. Only assert fields and handling advice defined by your workflow contract.
Use JSONPath such as $.priority. Prefer structured fields for model output; choose Final output text with exact-match, contains, or similarity only when wording itself is a product promise.
3. Add final-output and message rules for the Agent
Section titled “3. Add final-output and message rules for the Agent”The classification Agent’s structured result is stored as its final Agent message and becomes the evaluation’s final output. Use Validation rules → Final output field with $.priority = high to verify it; do not use Node output assertion → $.priority for this Agent. An Agent’s node-output surface contains messages, whose content is JSON text; path evaluation does not parse that text into another object.
When the product requires specific wording, use Agent message assertions for the classification Agent and Contains text to require an essential next-step explanation. Do not use word-for-word matching for normal variation in model expression.
4. Add tool and safety rules when needed
Section titled “4. Add tool and safety rules when needed”The CSV classification example needs no order tool. To test order lookup separately, first define a ticket_id workflow input, include "ticket_id": "TK-2025-001" in the Case, select lookup_order, and instruct the Agent to query that ticket. Then:
- Under Node tool assertions, select the classification Agent and
lookup_order; set call count to1. - If arguments matter, enable strict arguments and enter expected JSON such as
{"ticket_id":"TK-2025-001"}. - Add a Tool fixture for the same tool with arguments exactly matching the call (
{"ticket_id":"TK-2025-001"}here), and return fixed JSON that matches the tool’s output schema. Evaluation blocks unmatched calls instead of falling back to the live order system.
Under Safety assertions, choose final output, tool arguments, or tool results. Add forbidden field paths such as $.customer.phone, or forbidden text such as a real API key. Protect data that truly must not cross a boundary; do not prohibit normal business fields by mistake.
5. Save, run, and interpret the result
Section titled “5. Save, run, and interpret the result”Save the Case and run the Suite:
passed: execution completed and every enabled assertion passed.failed: execution completed but at least one assertion did not; open details to compare expected and actual values.error: the evaluation run itself could not complete; use run history to locate the node error first.skipped: the Case was disabled or did not participate in this run.
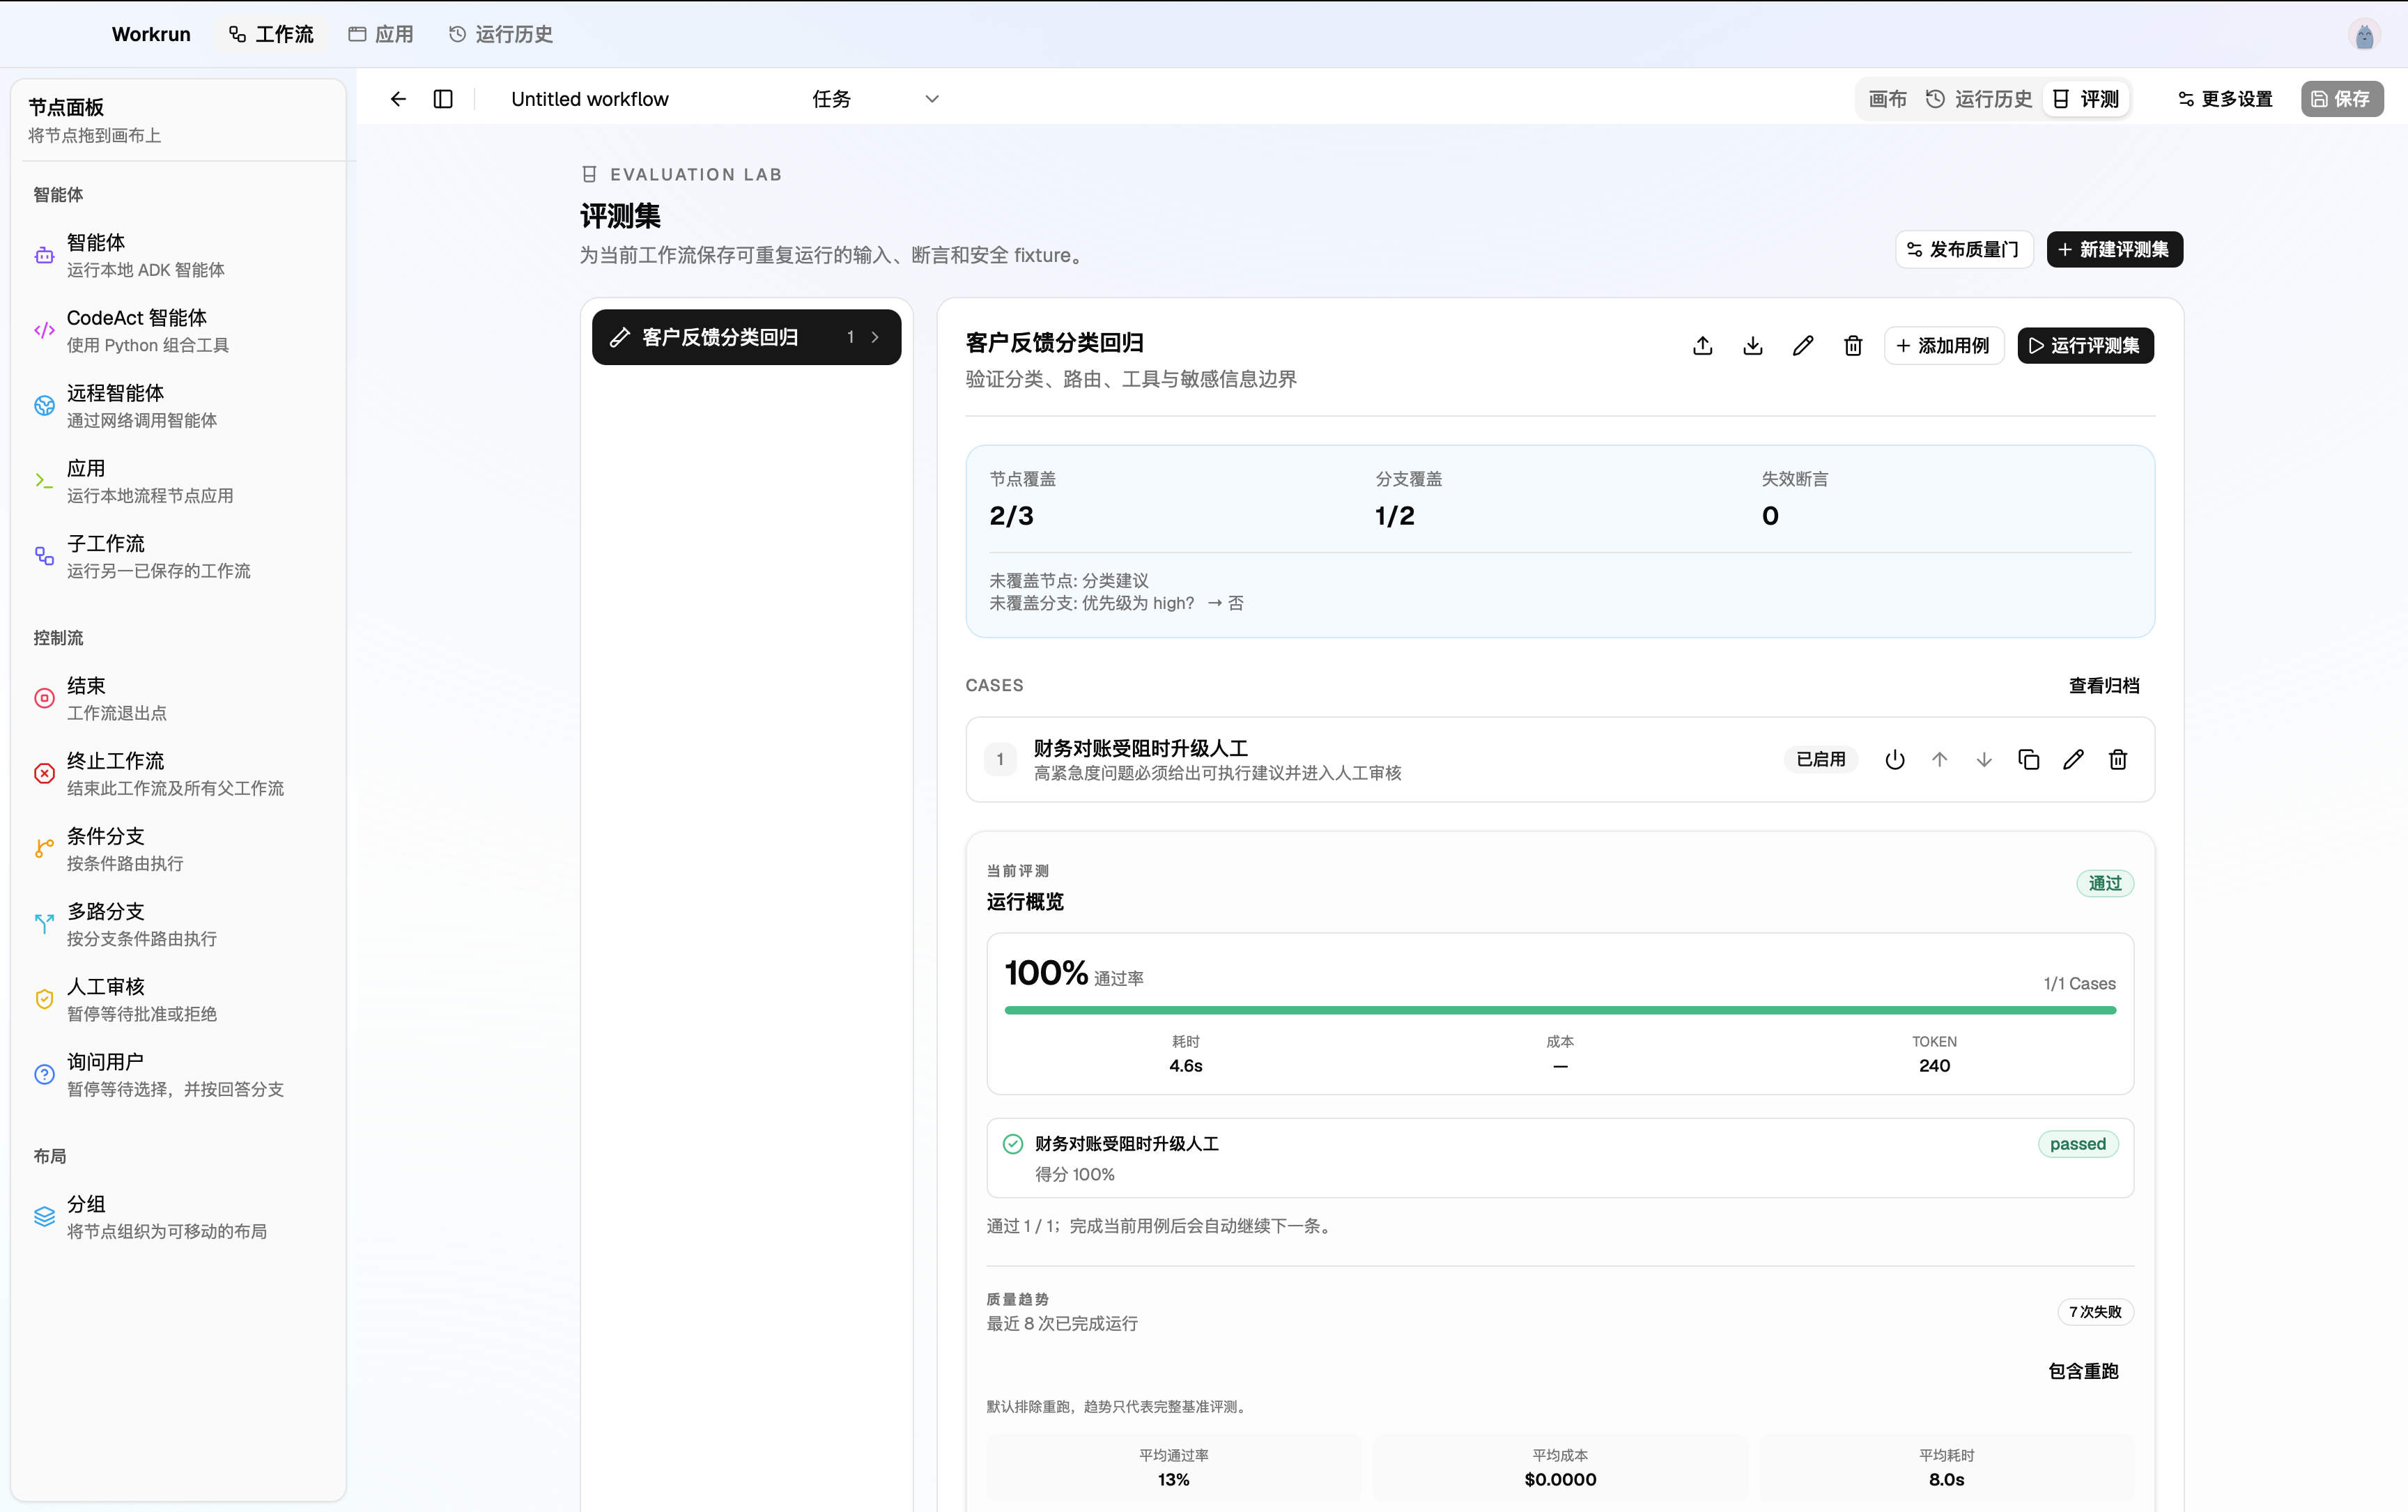
After this Case first passes, add an ordinary-feedback Case that asserts priority is not high. The two opposing Cases show that classification neither misses high-risk work nor labels everything urgent.
Choose the right assertion
Section titled “Choose the right assertion”| What you need to verify | Assertion | Useful example |
|---|---|---|
| Value delivered by the workflow | Final-output field / JSON assertion | priority equals high; category and recommendation are present. |
| Result produced by a control node | Node-output assertion | A condition node’s $.route equals the expected exit. Use final-output field assertions for an Agent’s structured result. |
| An Agent answer | Agent-message assertion | Exact match, contains text, or compares similarity to expected text. |
| Correct capability use | Node-tool assertion or tool trajectory | lookup_order is called exactly once with the expected arguments. |
| A prohibited leak or action | Safety assertion | Final output, tool arguments, or results omit a field path or text. |
Prefer final-output and node-output assertions because they are stable and explainable. Add tool assertions only when Agent tool use itself matters; do not freeze irrelevant implementation detail just to claim broader coverage.
Make tool evaluations repeatable
Section titled “Make tool evaluations repeatable”Real tools may read changing data or send, write, and delete. Tool App and MCP calls in evaluations must match a fixture by tool name and exact argument JSON. A fixture can also target an Agent node; node-specific fixtures take precedence over fixtures without a node. A match returns fixed JSON; a miss reports an error without executing the real tool. Even a no-argument call needs an explicit {} fixture.
Use tool assertions to check call order, counts, and arguments, and keep fixture results compatible with the tool’s output schema. Verify a real service through ordinary runs against a dedicated non-production target; test credentials do not bypass the evaluation fixture requirement.
Open a Case result, not only the pass rate
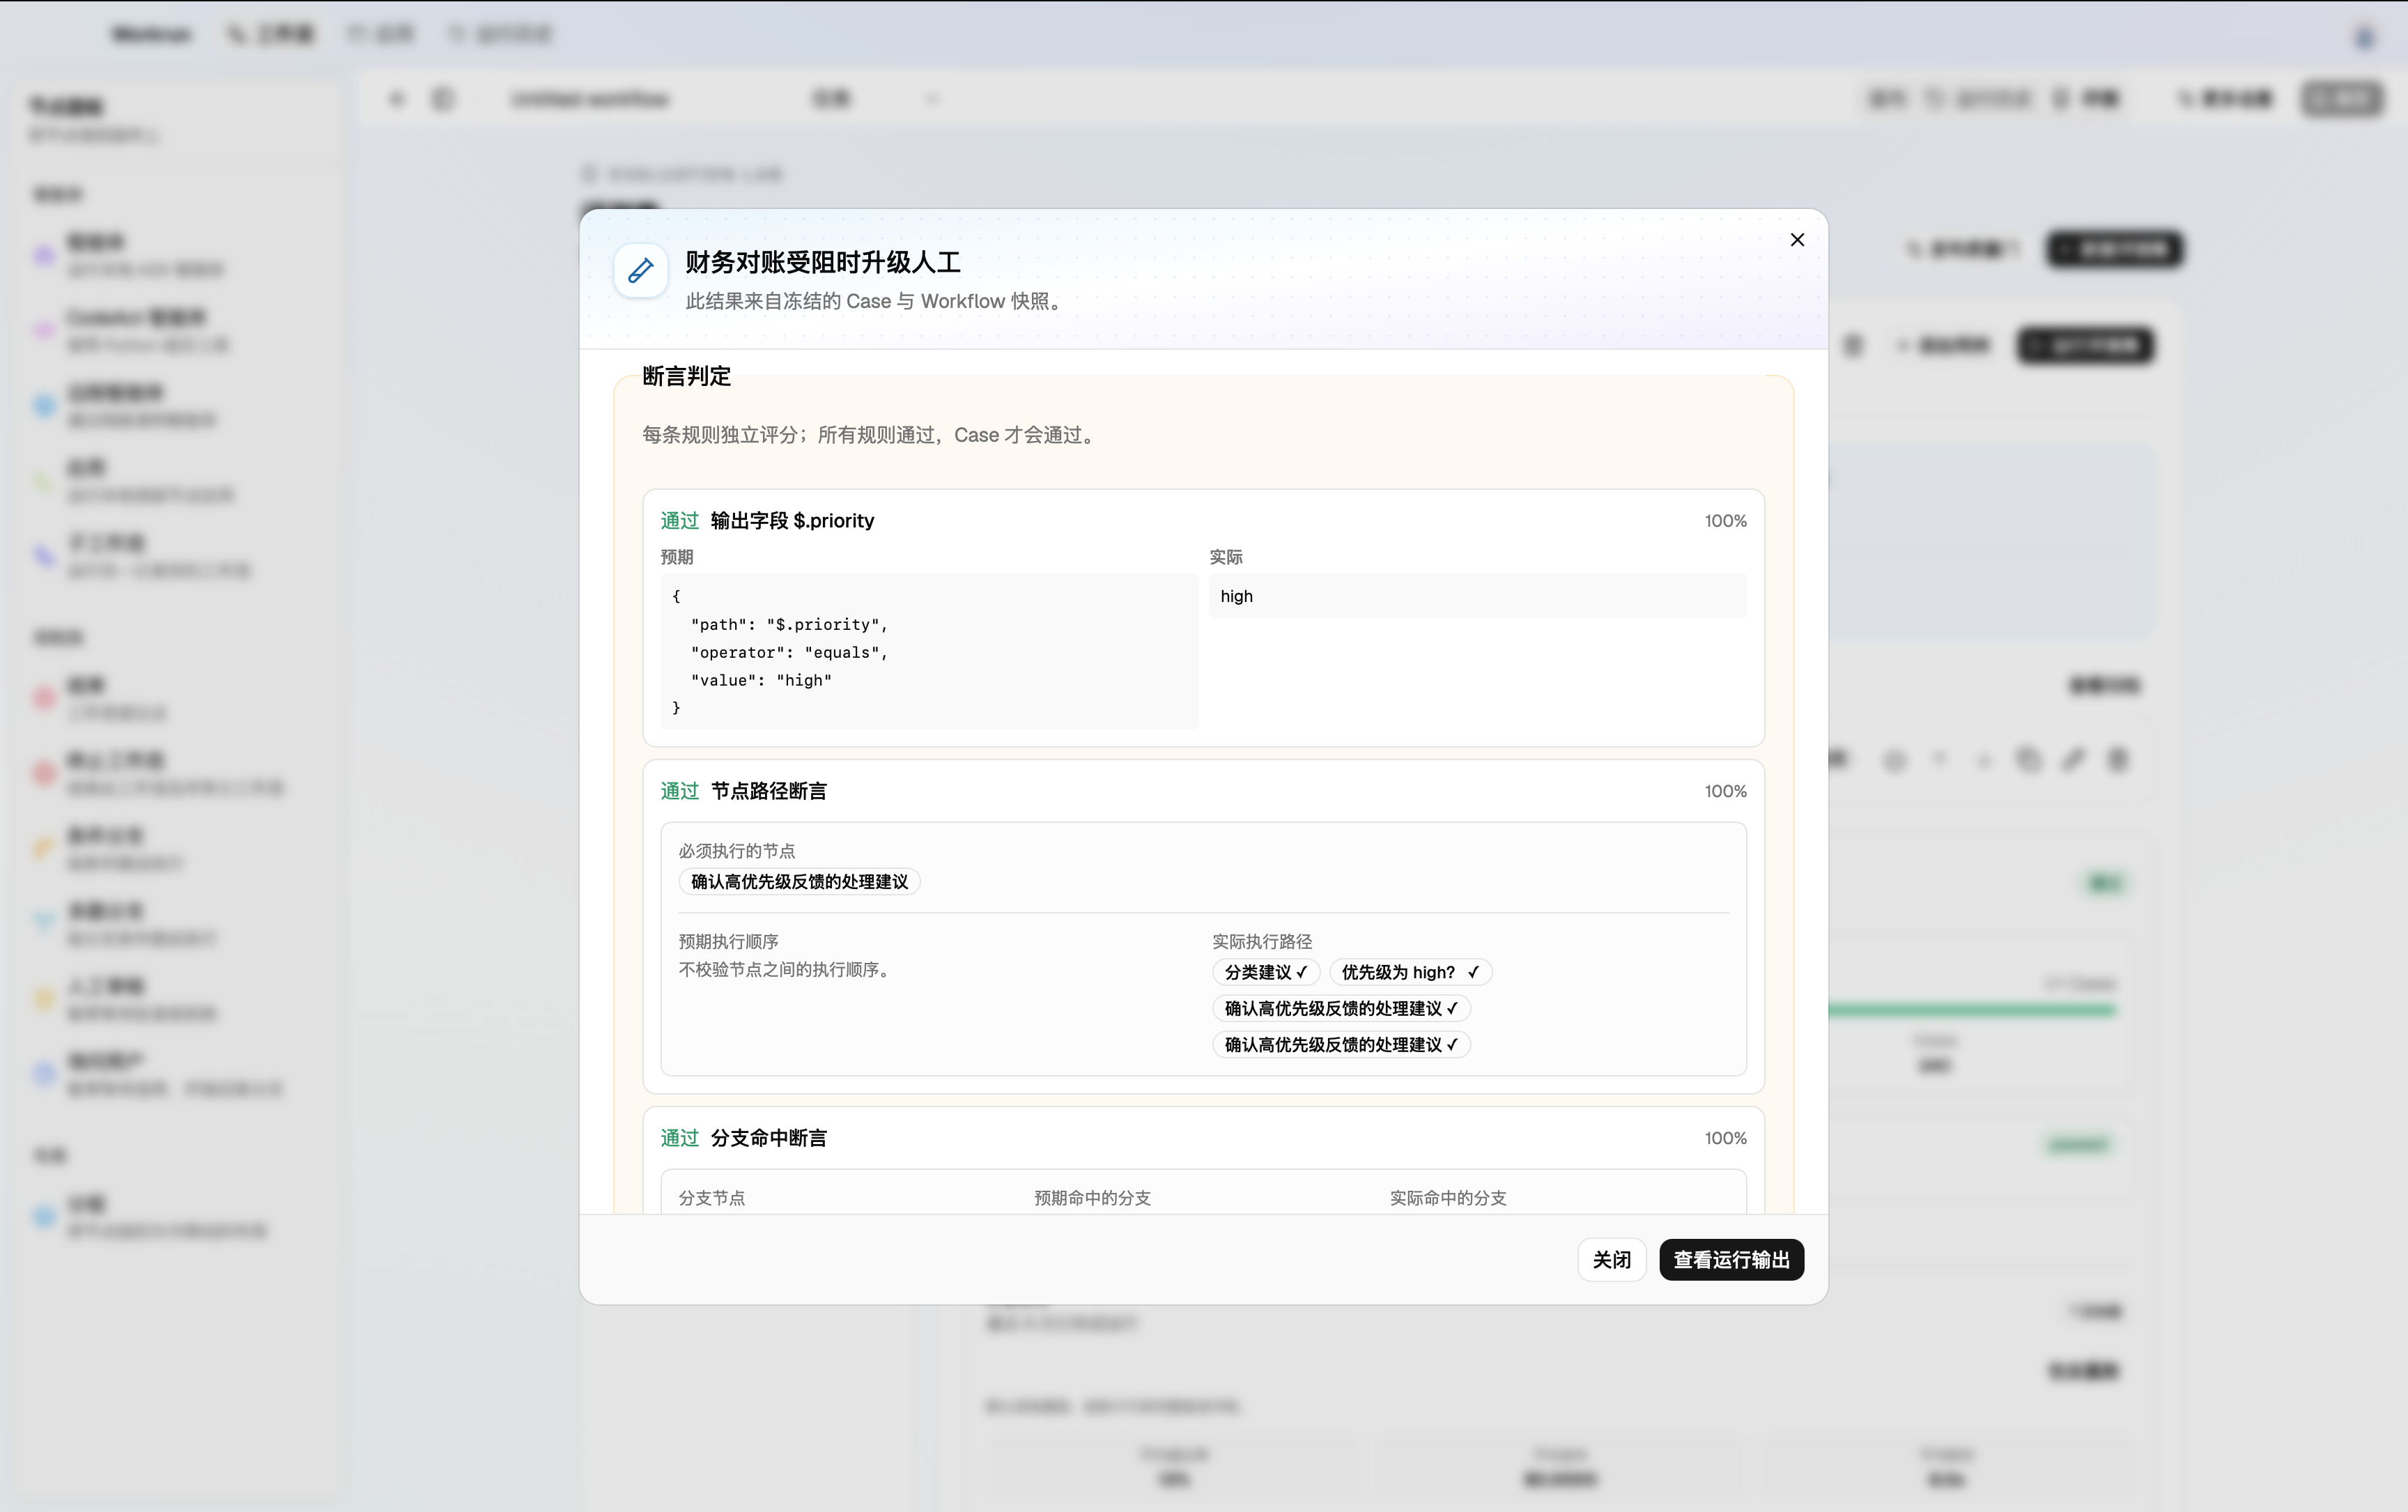
Section titled “Open a Case result, not only the pass rate”Open a Case detail whether it passed or failed, and confirm it verifies the intended behavior. Read it in this order:
- Execution status: did the run fail or cancel, or did it complete with an assertion failure?
- Failure reason and assertion result: which expected and actual values differ?
- Actual output and normalized trace: which Agent or tool call introduced the wrong value?
- Input and workflow snapshot: is this the intended Case and version, rather than mismatched test data or draft?
An error Case and a failed Case differ: the former usually means the workflow could not execute cleanly; the latter completed but did not meet its acceptance condition. For either, use Runs, debugging, and traces to inspect node-level evidence.
Use version comparison to decide whether a change can ship
Section titled “Use version comparison to decide whether a change can ship”After the same Suite has run against two workflow versions, version comparison marks every Case as added, removed, regressed, fixed, or persistently failing, and compares the individual assertion changes. Do not review only the aggregate pass rate:
- A new failure is candidate-version risk that should be explained or fixed.
- A fix should not come at the cost of a critical safety or tool assertion.
- A persistent failure needs an explicit repair task, or a documented reason to disable the Case temporarily.
- New Cases should capture real incidents and new product commitments.
Configure a publishing quality gate
Section titled “Configure a publishing quality gate”In Publishing quality gate, turn release expectations into a shared floor:
- Enable Require at least one evaluation to stop an unvalidated candidate from publishing.
- Select Required evaluation suites for publishing; only truly critical Suites should become a gate.
- Set a minimum pass rate so a small number of failures cannot disappear behind a total score.
- Set maximum cost and duration appropriate to the risk, so a correct but unsustainable version cannot publish unnoticed.
At publishing time, Workrun reads the latest evaluation for the current candidate workflow snapshot; a successful result from an older version cannot satisfy the new draft. A failed gate can be explicitly bypassed with a reason. That is an auditable exception, not the usual substitute for fixing the problem.
A practical first configuration is: enable Require at least one evaluation; set “Customer feedback classification regression” as required; set minimum pass rate to 100%; set a maximum duration that fits the team’s interaction expectation, such as 30 seconds; add a cost threshold only after the team has established a budget baseline. Do not make every Suite a publishing gate on day one—start with Cases that directly protect users, safety, and external side effects.
The minimum loop after every change
Section titled “The minimum loop after every change”- Use one run to understand the issue and identify behavior to protect.
- Add or update a Case that reproduces it.
- Change the workflow, prompt, model, tool, or schema.
- Run critical Suites and read evidence for every failure.
- Compare versions and confirm no new critical regression appeared.
- Publish through the quality gate, or retain a reasoned bypass record.
Evaluations do not replace human judgment. They make every judgment testable again after the next change.