Configure model access
You can also describe your goal on the start page, review a plan, and generate an editable workflow. See Build workflows through conversation. Plan approval and execution confirmation are separate steps.
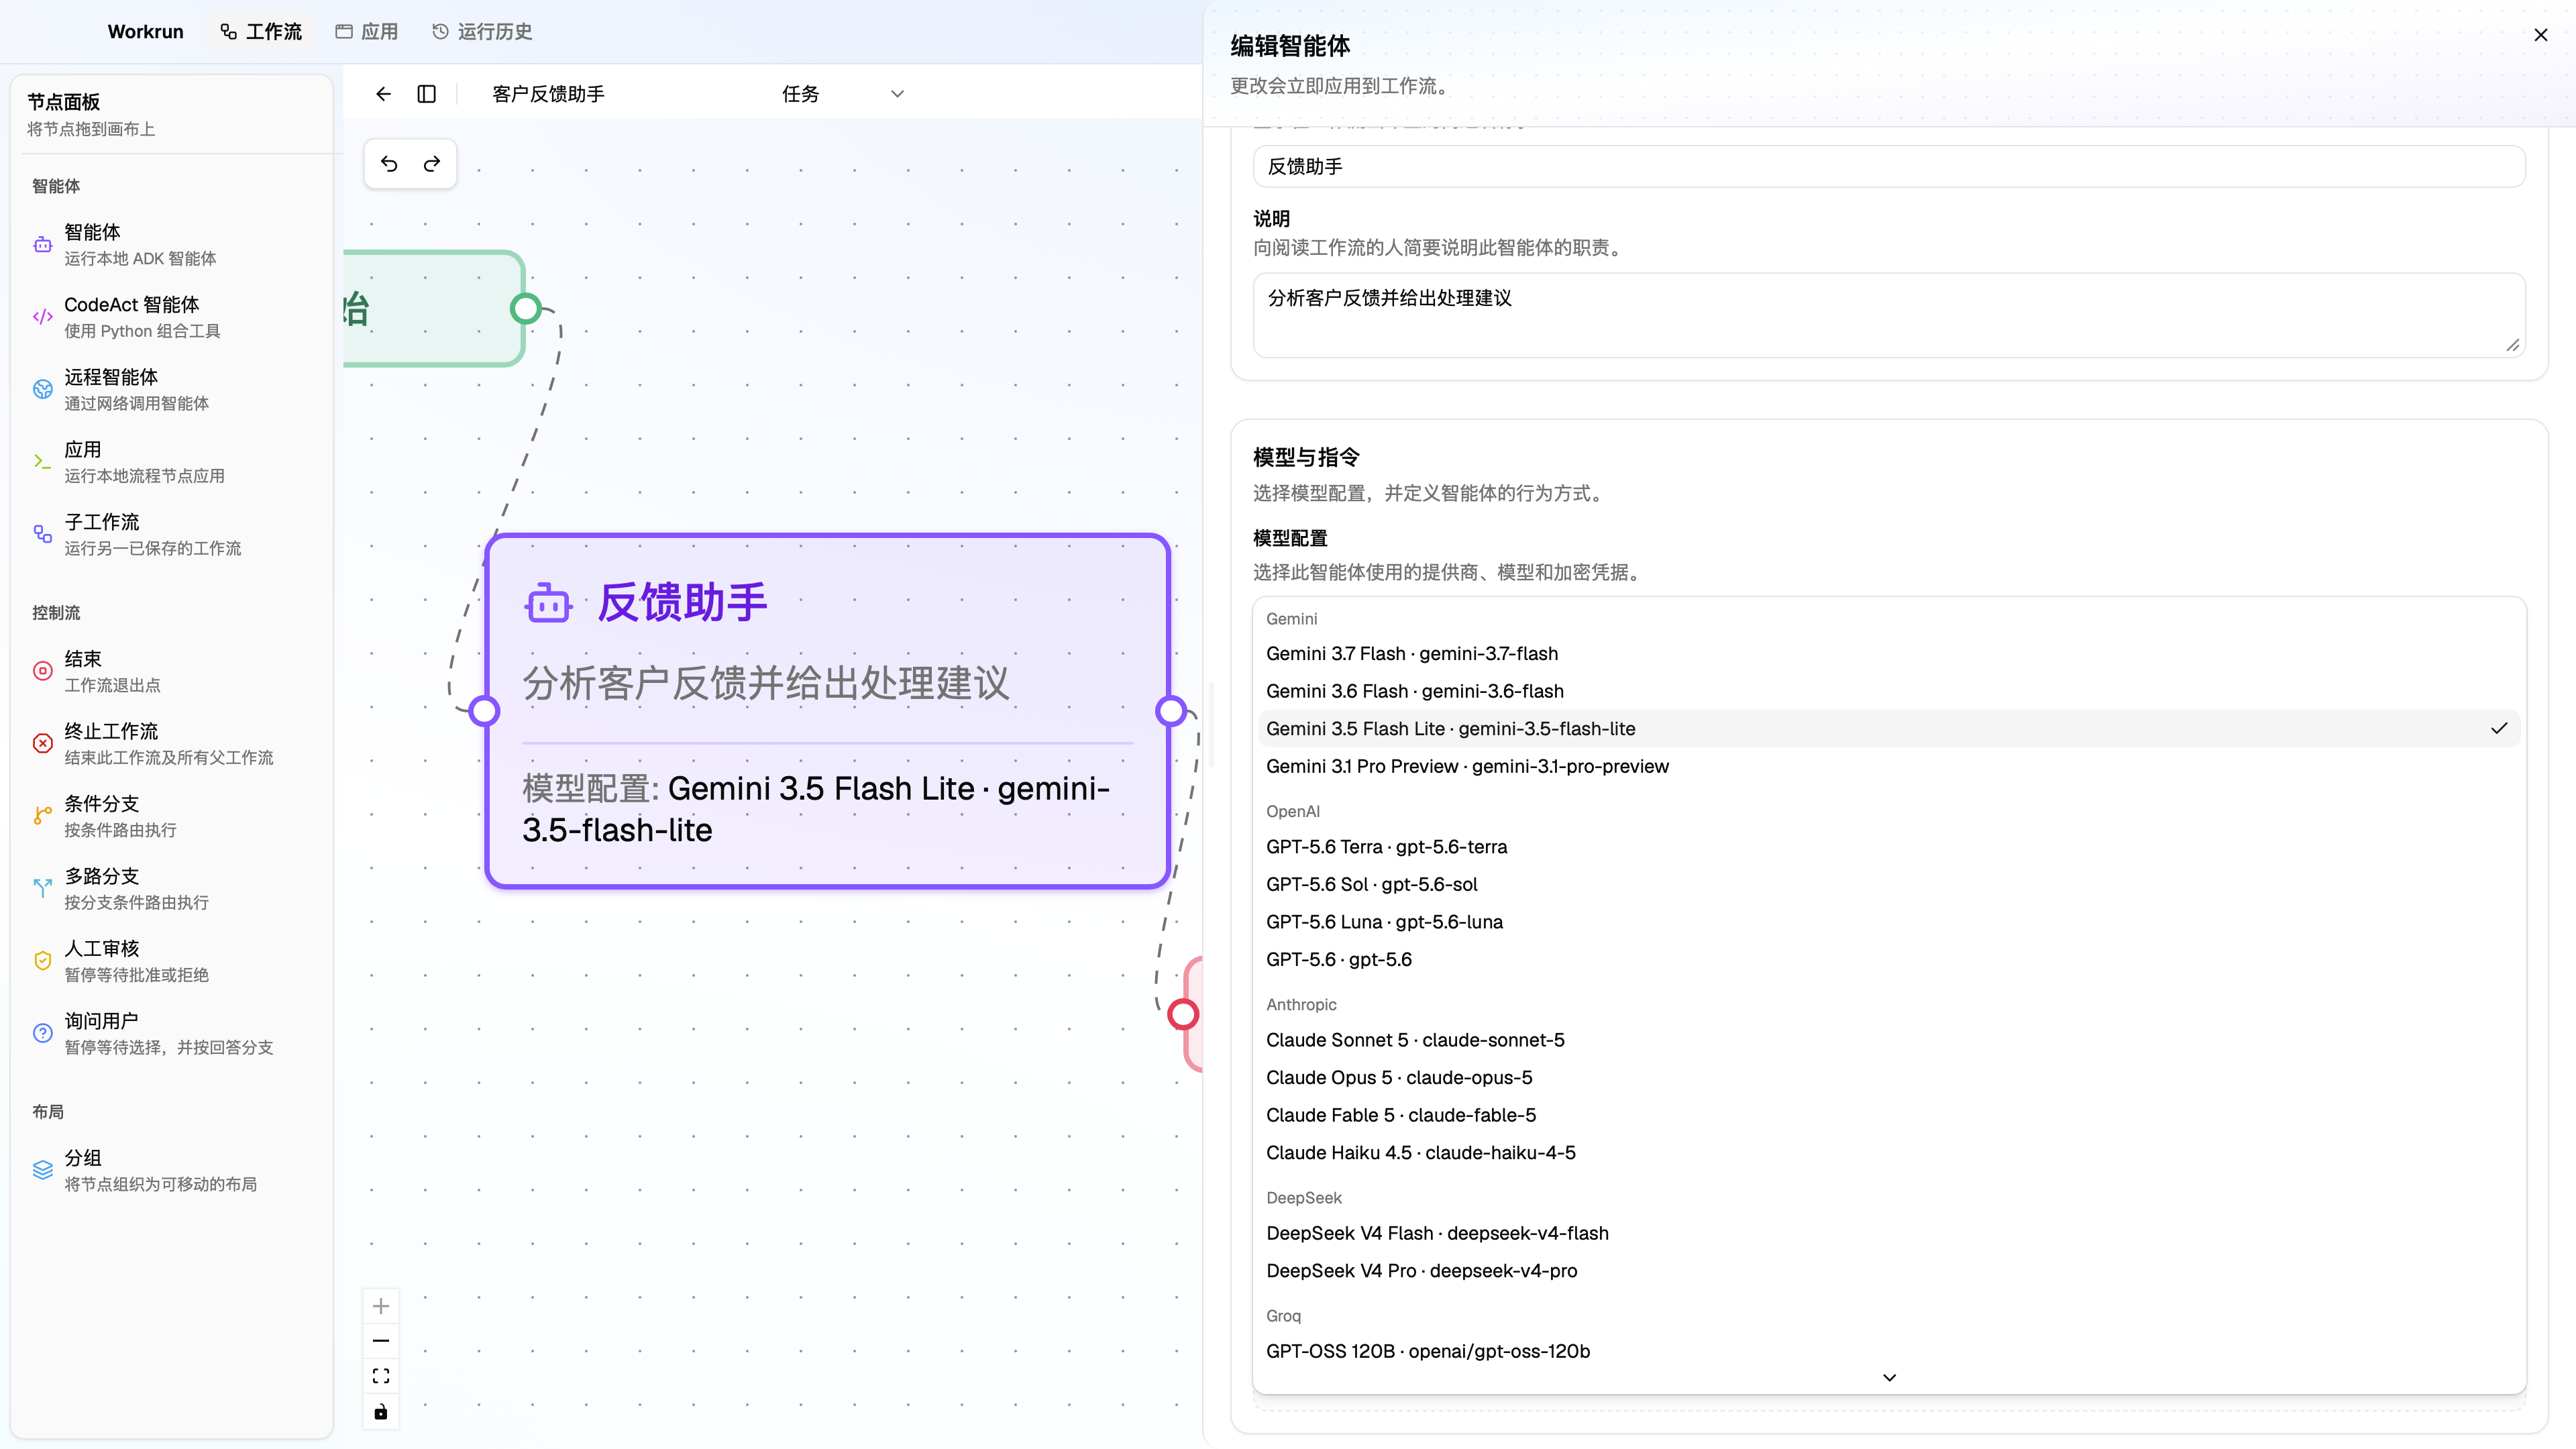
The model selector includes built-in Provider models and, after Team sign-in, the Server model catalog. Homepage assistants, Agent nodes, and CodeAct Agent nodes share this access mechanism without repeating model IDs in every workflow.
Add provider credentials
Section titled “Add provider credentials”- Open Settings → Models.
- Enter an API key on the row for the provider you want to use.
- Settings save automatically.
- Create or edit an Agent, then choose a built-in model for that provider under Model configuration.
Ollama uses an endpoint instead of an API key. The local default endpoint is normally sufficient; enter the applicable address for a remote deployment.
Team models: Workrun Server → LiteLLM
Section titled “Team models: Workrun Server → LiteLLM”- Connect to your team Server and sign in through Settings → Workspace.
- Select a model alias from the Server source on the homepage or in a node. The Server discovers the catalog from LiteLLM.
- Choose Chat Completions or Responses and a reported reasoning effort when the model supports them. Default reasoning does not send an extra effort parameter.
The desktop uses its current verified Workrun session; do not enter a LiteLLM Key there. Administrators configure a Team Virtual Key on Server, while LiteLLM holds Provider credentials. One Server currently maps to one LiteLLM Team, whose model permissions are shared by valid signed-in users.
Tool, image, structured-output, protocol, and reasoning-effort capabilities come from gateway metadata; unknown capabilities are not guessed. Model aliases must match the Team Key’s visible catalog. Responses uses client-side history replay, with store: false enforced by Server.
Team mode still permits explicitly selected local Provider connections. Direct requests use local credentials and bypass Server/LiteLLM; gateway failures do not automatically switch to direct access. Switching accounts or signing out interrupts team-model streams. Background recovery also requires the original user’s valid session; a persisted task does not authorize another account.
See Deploy Server, LiteLLM, and Langfuse. Old workflows do not automatically map personal models to team aliases: select the intended model, save, and publish a new version when needed.
Usage guidance
Section titled “Usage guidance”- One provider key can be used by that provider’s built-in models.
- Never put keys in node instructions, workflow inputs, or Python code.
- Configure an Agent’s name, role, instruction, tools, and generation parameters in the node inspector.
- After switching models, rerun the workflow with the same inputs to confirm the result.